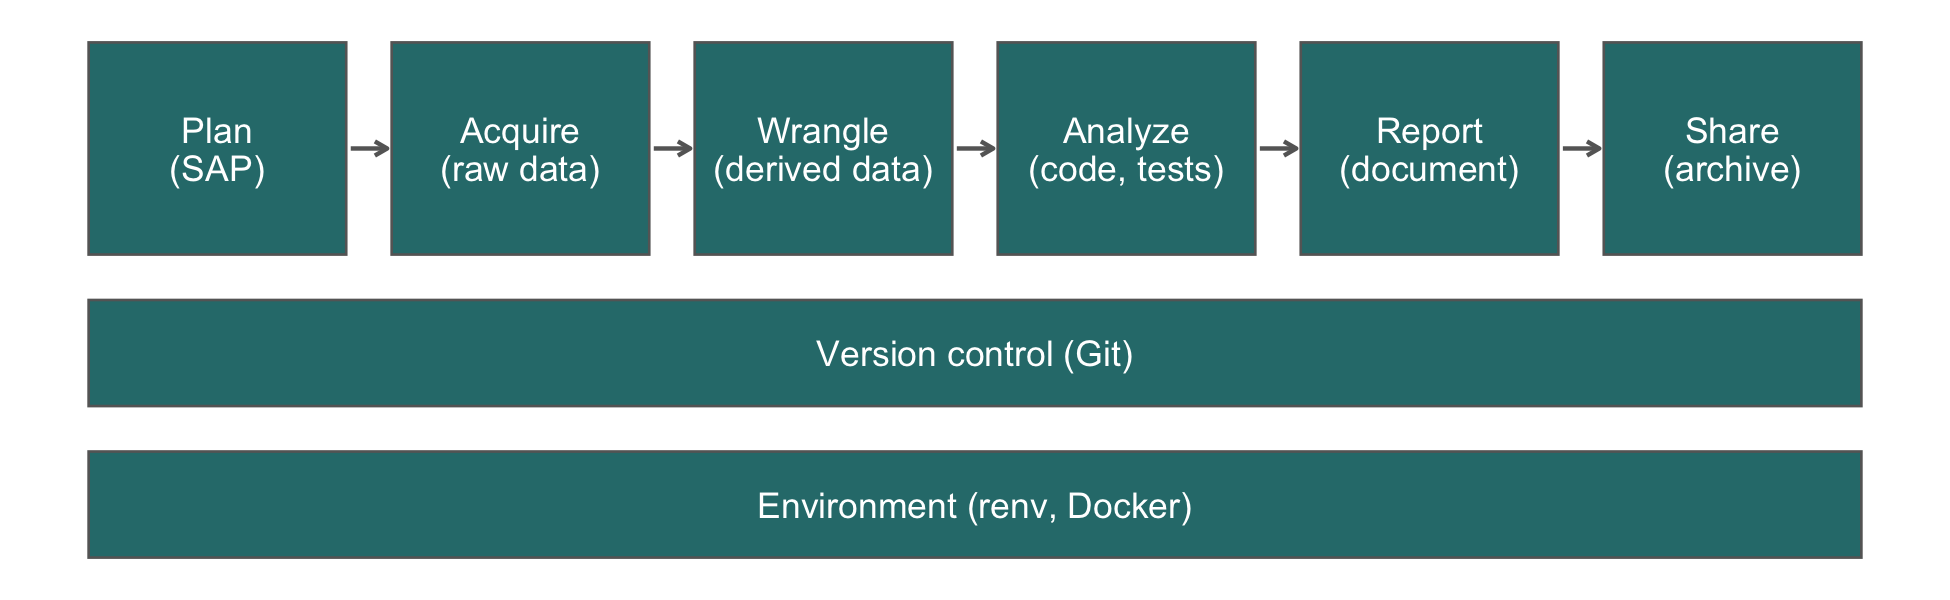
35 Capstone: HF-HOME from Export to Deposit
Every chapter so far has taught one step. Each tested that step on a fragment of the running study, chosen to make the step visible. An analysis does not arrive in fragments. It arrives as a raw case-report-form export with five sites’ conventions in it, a question someone needs answered, and a deadline. The steps also interact. A cleaning rule decides a denominator, and a join decides who is in the trial. A plan written after the outcome was seen decides nothing. This chapter is the capstone project of the second quarter. You take the HF-HOME study from the files in analysis/data/raw_data/hfhome/ to a deposited compendium. The compendium has a tagged analysis plan, executed tests, continuous integration, a one-page memo, and a response to a reviewer. You are graded on the twelve habits rather than on the estimate.
We shall not cease from exploration, and the end of all our exploring will be to arrive where we started and know the place for the first time.
T. S. Eliot, Four Quartets: Little Gidding (1942)
NoteIn this chapter
Reading time. About 20 minutes to read; ten weeks to do.
You’ll need. Every earlier chapter, and above all Chapter 30, whose Table 30.1 is the worked model for the milestone table below. The codebook for the data is analysis/data/raw_data/hfhome/README.md; read it before the first milestone.
You’ll be able to.
- Plan a complete analysis as a sequence of milestones, each with a deliverable and a test of whether it is done.
- Take a multi-table clinical export from raw files to a deposited, rebuildable compendium without editing a raw file or typing a number.
- Write a one-page memo and a response to a reviewer that a stranger can check against the compendium.
- Assess your own work, and a colleague’s, against the twelve habits.
Outline.
NoteReady to start?
The capstone cannot be skipped, but these three questions show whether the earlier chapters are in hand. The answers are in Section 35.10.
- Which file in the HF-HOME export must not be read by any code until the analysis plan is tagged, and how would a reviewer confirm that it was not?
- Name three of the planted pathologies in
crf_export.csvand the chapter that taught you to find each. - A colleague clones your deposit in five years. Which three files must exist for them to rebuild your memo’s numbers?
35.1 The project
HF-HOME is the synthetic two-arm trial that has run through the book. It enrolled 2,432 patients discharged after a heart-failure admission. They were randomized 1:1 to home-health visits within seven days or to usual care, stratified by site and ejection-fraction stratum. The primary outcome is readmission or death within 30 days. The data are eight files: seven clean tables and the raw export crf_export.csv. The export carries the five sites’ conventions for dates, sex codes, missing values, and identifiers. The codebook lists every planted pathology and the chapter that taught you to find it. The analysis plan of Section 26.8 fixes the estimand.
The question you answer is the one the principal investigator (PI) asked at intake (Section 3.2): does a home-health visit within a week of discharge reduce 30-day readmission or death, and should the health system pay for it? You deliver seven artifacts:
- A compendium in a private Git repository, with the five pillars (Section 11.3), the raw files copied in unchanged, and a log in the README of each use of a language model and how its output was checked.
- A statistical analysis plan (SAP) and a data management and sharing plan (DMSP), tagged before any code reads the outcome file.
- A derived analysis dataset rebuilt by one command from the raw files, and a de-identified release of it.
-
A test suite in
inst/tinytest/, run by continuous integration (CI) on every push. - A report in Quarto in which every number is computed.
- A one-page memo to the PI and a response to the reviewer of your deposit.
- A deposit: a tagged release archived with a digital object identifier (DOI).
Work in the Zenodo sandbox (sandbox.zenodo.org) rather than the production service. The sandbox issues test DOIs, and a synthetic classroom dataset does not belong in the permanent scholarly record. Everything else is real. The data are synthetic, but demographics.csv contains direct identifiers in the form real ones take. You handle it as protected health information. That is, it never leaves the compendium, never enters a prompt to a language model (Section 12.3), and never appears in the deposit.
WarningPitfall
The codebook has already told you the answer. The README beside the data reports the observed event rates in each arm, because it documents the generator. In a real trial the outcome file would not exist on your machine until the SAP was signed. Here the file is present from the start, and keeping it sealed is up to you. Do not read the README’s Design section until your SAP is tagged. The tag is evidence only of the order of commits. A plan written by someone who already knows the result does not pre-specify anything.
NoteCheck
Question. Why does the brief require the raw files to be committed unchanged, when the clean tables beside the export would save a week of work?
Answer. Habit 2 treats the raw export as evidence and everything after it as a build product. The clean tables are the generator’s answer to the cleaning problem. Using them would skip the steps in which the analysis’s denominator is decided (Section 13.2, Section 15.4, Section 16.4). Starting from crf_export.csv makes every one of those decisions a line of code a reviewer can read. You may use the clean tables afterward as an oracle in your tests.
35.2 Milestones
Table 35.1 is the capstone’s version of Table 30.1. Each row is a milestone with a deliverable, the chapter that taught it, the habits it exercises (numbered as in Section 1.6), and a ‘done when’ criterion that someone other than you can check. A milestone is done when its criterion is met, not when the work feels finished.
| Milestone | Deliverable | Taught in | Habits | Done when |
|---|---|---|---|---|
| 1. Intake |
intake.md: the question in one sentence, the decision it informs, the estimand, and the scope of work |
Section 3.2, Section 3.3 | 5, 11 | The PI (or the instructor) signs off on the question as written |
| 2. Scaffold | Private repository with the five pillars; raw files committed with checksums | Chapter 11, Chapter 9, Chapter 10, Chapter 7 | 1, 2, 3, 4 | The audit of Section 11.7 passes and raw_data/ matches its recorded checksums |
| 3. Acquire and clean | A script or targets pipeline from crf_export.csv to a typed, recoded baseline table |
Section 13.2, Section 15.4, Section 16.4, Section 24.2 | 2, 7, 8 | One command rebuilds the table from raw; every site’s dates, sex codes, IDs, and missing-value codes resolve, asserted in code |
| 4. Plan | SAP and DMSP, tagged sap-v1.0
|
Chapter 26, Section 26.6, Section 26.17 | 3, 5 | The tag predates the first commit that reads outcomes.csv, as git log shows |
| 5. Tests and CI | A tinytest suite on the cleaner, the joins, and the primary estimate; a GitHub Actions workflow |
Section 27.7, Section 27.8, Section 27.9 | 8, 9 | A planted bug, such as undoing the Site E identifier repair, turns the CI run red |
| 6. Join and de-identify | The analysis dataset from the seven tables; a de-identified release | Section 18.5, Section 22.1 | 2, 6, 8 | Each join declares its relationship and logs its row counts; the orphan lab patient and duplicate lab rows are handled by a stated rule; the release passes the Safe Harbor checks |
| 7. Analyze | The primary analysis and the pre-specified sensitivity analyses, with figures | Section 26.8, Section 21.6, Section 20.6 | 5, 7, 12 | Every result is labeled pre-specified or exploratory, and every figure regenerates from derived data |
| 8. Report | A Quarto report of methods and results | Section 23.4, Section 33.3 | 10 | Changing a raw value changes the prose; no estimate in the source is typed |
| 9. Memo | A one-page memo to the PI | Section 33.4, Section 33.2 | 10, 11 | The answer is in the first sentence, the verb matches the design and the interval pattern, and it fits on one page |
| 10. Deposit | Tagged release, README, de-identified data, sandbox DOI | Section 7.5, Section 34.2 | 1, 3, 4 | A classmate rebuilds the report from the DOI in a fresh container |
| 11. Review | A written review of a classmate’s deposit | Section 33.9, Section 8.4 | 9, 11 | Every comment cites a file and line, and each is ranked by whether it could change the conclusion |
| 12. Respond | A response to the review you received, and a revised release | Section 33.8 | 3, 10, 11 | Every comment is numbered, quoted verbatim, and answered with the change made and where, or with the reason no change was made |
Milestones 3 and 6 are where most of the time goes, as they are in practice. The codebook lists the export’s pathologies so that you know what to look for. It does not excuse you from looking. The test of milestone 3 is that your code finds each pathology from the data and refuses to proceed if a new one appears. This is habit 8 applied to a whole file. The immortal-time trap in visits.csv belongs to milestone 7. A per-protocol comparison of patients who received a visit answers no question the trial was designed to answer (Section 26.2). Your SAP should say so before you are tempted.
TipVerification
Before milestone 10, run the clean-room check. Clone the repository into a new directory, build the image, and render the report inside it, without using anything from your working copy (display-only, because it builds an image):
git clone --branch v1.0 <your-repo> /tmp/hfhome-check
cd /tmp/hfhome-check
make docker-build
make docker-render REPORT=analysis/paper/paper.qmd
Then compare the rendered estimates with the ones in your memo. If the build fails, a dependency is not pinned. If it succeeds with different numbers, something in your working copy was not committed. Treat either as a milestone 2 finding and fix it.
ImportantLLM prompt
Context. Attached: the file tree of my compendium, my
DESCRIPTION, my test file names and assertion messages, and the milestone table below. No data are attached.Task. For each milestone, list what a reviewer would open to check the ‘done when’ criterion, and name any criterion my tree gives no evidence for.
Constraints. Do not invent files that are not in the tree.
Check what it returns. Open each file it names and confirm it exists and does what the model says. The typical failure is a plausible list of checks against files that do not exist. The prompt sends structure and no data, so it is safe under habit 12. Pasting rows of demographics.csv would not be.
NoteCheck
Question. Milestone 4 comes after milestone 3. Does cleaning the baseline data before the SAP is tagged violate pre-specification?
Answer. No, provided the cleaning does not touch the outcome. Pre-specification protects the analysis from choices made in knowledge of the result. Cleaning the baseline covariates blind to the outcome is how trials work. It often informs the SAP (for example, how many patients lack a systolic blood pressure). What the tag must predate is the first code that reads outcomes.csv. A reviewer checks it with git log --follow -- <file> on the scripts that read the outcome, compared with git show sap-v1.0.
35.3 A ten-week schedule
The second quarter reads Parts IV to VIII at about two chapters a week, and the capstone runs alongside the reading. Each milestone falls in the week its chapter is taught or soon after. There are three exceptions. The intake, the pinned environment (Chapter 9, Chapter 10, Chapter 11), and the cleaning use first-quarter chapters, so they start at once. The reading is lighter in the first three weeks to leave room for them. Table 35.2 is a suggestion. An instructor with a shorter term can drop milestone 11 and have students respond to the instructor’s review instead.
| Week | Read | Capstone work | Due at the end of the week |
|---|---|---|---|
| 1 | Chapter 23 | Read the codebook; intake conversation; create the repository | Milestone 1 |
| 2 | Chapter 24 | Pin the environment; commit raw files and checksums | Milestone 2 |
| 3 | Chapter 25 | Read and recode the export as a pipeline, outcome sealed | Milestone 3 |
| 4 | Chapter 26, Chapter 27 | Write and tag the SAP and DMSP; tests on the cleaner; CI | Milestones 4 and 5 |
| 5 | Chapter 28, Chapter 29 | Join the seven tables; de-identify; optionally derive an ADSL | Milestone 6 |
| 6 | Chapter 30, Chapter 31 | Primary and sensitivity analyses; figures | Milestone 7 |
| 7 | Chapter 32, Chapter 33 | Report with computed numbers; draft the memo | Milestones 8 and 9 |
| 8 | Chapter 34, this chapter | Clean-room check; tag v1.0; sandbox deposit |
Milestone 10 |
| 9 | (none) | Review a classmate’s deposit | Milestone 11 |
| 10 | (none) | Respond, revise, tag v1.1; a five-minute talk (Section 33.5) |
Milestone 12 |
Two features of the schedule are deliberate. First, the SAP is due in week 4, after the cleaning and before the outcome is unsealed. The order of commits then carries the pre-specification. Second, the deposit is due two weeks before the end. A review of a deposit is only useful if there is time to act on it. The response in week 10 is where most students first discover what their README does not say.
35.4 Assessment
The capstone is graded on the habits rather than on the estimate. Two students who reach different conclusions from the same data can both earn full marks. A student whose estimate matches the generator’s can fail. The reason is that the evidence of competence is the trail that produced the estimate. Table 35.3 gives, for each habit, what the grader inspects and three levels.
| Habit | What the grader inspects | Not yet | Meets | Exemplary |
|---|---|---|---|---|
| 1. Compendium is the unit | Repository layout and deposit | Code, data, or environment missing from the deposit | Five pillars present; the report rebuilds from the release | A stranger rebuilds it from the DOI alone, following only the README |
| 2. Raw data are evidence |
raw_data/, checksums, build scripts |
A raw file edited or overwritten | Raw files unchanged and checksummed; derived data regenerated | Derived data are not committed at all; one command makes them |
| 3. Version control from day one | Commit history and tags | A few large commits near the deadline | Regular commits with informative messages; sap-v1.0 and v1.0 tags |
History reads as the project’s audit trail; the response cites commits |
| 4. Pin the environment |
renv.lock, Dockerfile |
Unpinned packages or base image | Lockfile restores; image pinned by version | Clean-room check documented and passing in CI |
| 5. Pre-specify, then tag | SAP, tag date, git log on outcome scripts |
SAP written or changed after outcomes were read, without an amendment | SAP tag predates outcome code; deviations listed | Every deviation dated, justified, and reported in the report and memo |
| 6. Count before and after every join | Join code and its log | Joins without declared relationships |
relationship and unmatched declared; row counts logged |
Each excluded or unmatched row is accounted for in a CONSORT-style count |
| 7. Convert late, validate early | Reading and typing code | Types guessed at read time; silent coercion | Columns read as text, converted once, validated before modeling | Validation failures stop the pipeline with a message naming the site and row |
| 8. Plausible bugs are expensive | Assertions in the pipeline | No assertions | Assertions after each join and transformation | Each planted pathology has an assertion that would catch its recurrence |
| 9. Test the statistics, not the shape |
inst/tinytest/ and CI |
Tests only check that columns exist | Tests check denominators and re-derive the primary estimate | A planted bug is shown to fail the suite, in a recorded CI run |
| 10. Every number is computed | Report and memo source | A typed estimate in either | Every number inline or from a computed table | The memo is rendered from the compendium, and its numbers are asserted |
| 11. Lead with the answer; match the verb | Memo, report, response | Chronological memo; causal verb unlicensed by the design or interval | Answer first; verb matches design and interval pattern | Caveats ranked by whether they could change the conclusion |
| 12. Model output is a hypothesis | AI-use log in the README | LLM output used unchecked, or data sent to a model | Log lists each use and how its output was verified | Log shows a model error caught by the stated check |
Score each row 0, 2, or 3, for a maximum of 36. The gap between ‘not yet’ and ‘meets’ is wider than that between ‘meets’ and ‘exemplary’ on purpose. The rubric rewards doing every habit adequately over doing a few very well. Reviewers and regulators judge an analysis the same way. Use the same rubric for milestone 11, so that the review you write and the review you receive use the same terms.
NoteCheck
Question. A student’s memo reports the primary estimate correctly, but the report states it with a typed number that matches the computed one. Which row is affected, and does it matter if the numbers agree?
Answer. Row 10, scored ‘not yet’. Agreement today is not the criterion. The criterion is that the number cannot disagree tomorrow. A typed number survives the next data correction unchanged, and the response to reviewers in milestone 12 is usually where that correction arrives.
35.5 The habits you take forward
The book has taught a great many tools, and tools go out of date. The habits do not. Here they are once more, as Section 1.6 first set them out and as the rubric above grades them:
- The compendium is the unit. Code, data, environment, and document travel together, in one declared structure.
- Raw data are evidence; derived data are a build product. Never edit what you received; regenerate everything else.
- Version control from day one. Every change is a commit; tag what you submit.
- Pin the environment. Snapshot writes the lockfile, restore reads it, and a container pins what the lockfile cannot.
- Pre-specify, then tag. Write the analysis plan and tag it before you see the outcome.
- Count before and after every join. Declare the relationship you expect and let the code refuse anything else.
- Convert late, validate early. Keep types loose while reading and cleaning; check them hard before modeling.
-
A bug that produces a plausible number is the expensive kind. A bug that produces
NAannounces itself; write the assertion that makes the quiet one loud. - Test the statistics, not the shape. A test that only checks that a column exists passes on a wrong answer.
- Every number in the prose is computed. Typed numbers drift from the analysis that produced them.
- Lead with the answer, and match the verb to the design. Say what you found first; say ‘is associated with’ unless the design licenses ‘causes’.
- Every model output is a hypothesis until verified. Send a language model structure, not data, and check what it returns as you would check a junior colleague’s work.
All twelve serve the idea in Section 1.6: make silent failures loud. If you take only one habit from this book, take the first. That is, every analysis lives in a compendium. Most of the others build on it. However, a compendium alone prevents none of the failures of inference in Chapter 32. The compendium need not be built by any particular tool. Chapter 11 assembles it by hand and treats zzcollab as one optional way to automate the assembly.
35.6 Why reproducible research, answered
Chapter 2 opened with the Duke genomic signatures. There, gene lists were offset by one row and labels were reversed. The errors stopped no code and produced results that looked like findings. They were exposed only by months of forensic reconstruction by two statisticians outside the team. The chapter’s title asked why anyone should do the work this book asks for. The capstone is the answer in practice.
A reviewer of your HF-HOME deposit does not reconstruct anything. They clone a tagged release, build a pinned environment, and run one command. Every number in your memo is then rebuilt from the raw export in front of them. If an identifier was misread at Site E, an assertion says so by name. If the plan changed after the outcome was seen, git log says so by date. The Duke errors were of exactly these kinds. In a compendium like yours they are found in an afternoon, often by the analyst, before any patient is affected. Reproducibility cannot guarantee correctness, as Section 2.6 and Chapter 32 show. What it provides is the ability of anyone, including you in five years, to find out quickly whether the analysis is correct.
35.7 Rules of thumb
- Habit 5: pre-specify, then tag. Seal the outcome until the SAP is tagged; the order of commits is the evidence.
- Habit 1: the compendium is the unit. Run the clean-room check before you deposit, not after the reviewer does.
- Habit 11: lead with the answer. Write the memo’s first sentence before the report; if you cannot, the analysis is not finished.
35.8 Cheat sheet
| Milestone | Command or file | Check |
|---|---|---|
| Scaffold | Layout of Section 11.4, or zzc tidyverse
|
Pillar audit passes |
| Checksums | shasum -a 256 analysis/data/raw_data/hfhome/* |
Matches the committed record |
| Clean | targets::tar_make() |
targets::tar_outdated() is empty |
| Tag the plan | git tag -a sap-v1.0 -m 'SAP v1.0' |
Tag predates outcome code |
| Join | left_join(..., relationship = 'one-to-one', unmatched = 'error') |
Row counts logged |
| Test | tinytest::run_test_dir('inst/tinytest') |
A planted bug fails |
| Render | make docker-render REPORT=analysis/paper/paper.qmd |
Numbers change when data change |
| Release |
git tag -a v1.0 -m 'Deposit'; GitHub release with Zenodo sandbox |
Test DOI resolves |
35.9 Further reading
Three books repay a first read soon after the capstone; the reading that follows them depends on your applied area.
- R Packages, 2nd ed. (Wickham & Bryan, 2023), because a compendium is a package in all but name.
- Happy Git with R (Bryan, 2019), for the Git habits the capstone leans on.
- Reproducible Research with R and RStudio, 3rd ed. (Gandrud, 2020), for the publishing pipeline.
What the book left out, including statistical theory, Bayesian computation, machine learning, and causal inference, is listed in Chapter 1, with the companion volume as the next step.
35.10 Prerequisites answers
-
outcomes.csv. A reviewer runsgit logon every script that reads it and compares the earliest such commit with the date of thesap-v1.0tag (git show sap-v1.0); the tag must come first. The codebook’s Design section, which reports the observed rates, is under the same seal by agreement. - Any three of: a byte-order mark and CRLF line endings (Section 13.2); leading zeros lost from Site E’s identifiers (Section 13.2, Section 18.3); four date formats by site (Section 16.3); four sex codings (Section 15.2); and three codes for a missing number, including
-99(Section 21.2). - The lockfile (
renv.lock) and the Dockerfile, which pin the environment, and the source of the report or memo, which computes every number from the raw data; the raw data and the scripts between them and the report must be in the deposit too, or the README must say how to obtain them.