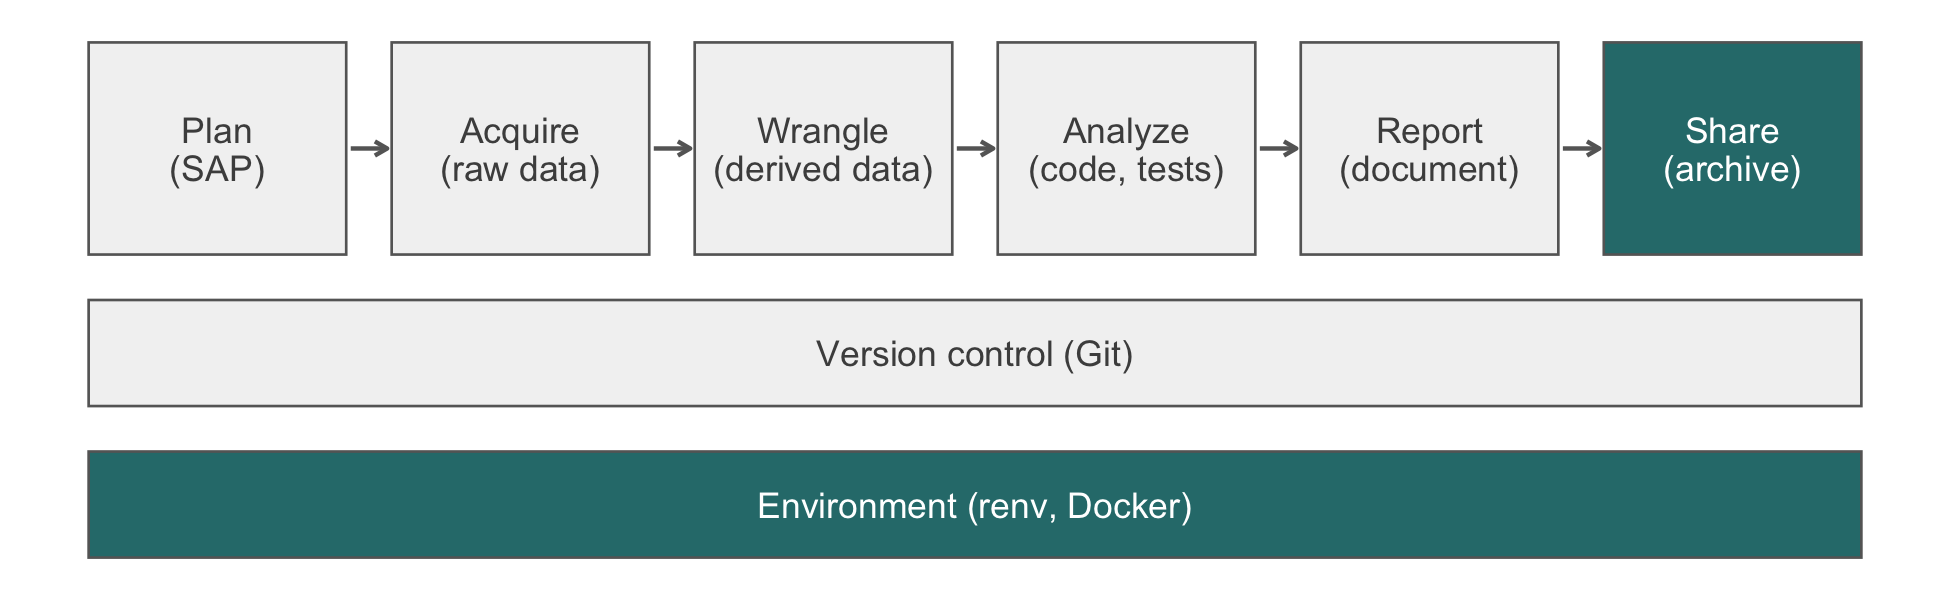
11 Assembling the Compendium
A collaborator clones your repository, runs the analysis script, and gets a p-value of 0.06 where your draft reports 0.04. Nothing errors. Over two days the two of you find three differences. Her R packages are a year newer than yours. The cleaned dataset in the repository was produced by a version of the cleaning script you have since edited. And one exclusion was made by hand in a spreadsheet that never entered the repository. Each difference is a piece of the study that did not travel with the code. Even with the packages pinned, the same rerun can still differ. Suppose the repository could not hold the outcomes file, and the README said to copy it from a shared drive. If that drive now holds a later, corrected extract, nothing in the repository could tell either of you that the inputs differed. A research compendium is the arrangement in which everything needed to produce the paper, from the raw data to the environment, lives in one directory. Its layout is one a stranger can read. The Five Pillars are the checklist that says every layer the answer depends on is pinned. This chapter sets out what a compendium is and where its files go. It then assembles the pillars, builds the result, and audits it. The aim is that the collaborator’s rerun either matches or tells you why not.
We introduce the concept of a compendium as both a container for the different elements that make up the document and its computations (i.e. text, code, data, …), and as a means for distributing, managing and updating the collection.
Robert Gentleman and Duncan Temple Lang, Statistical Analyses and Reproducible Research (2007)
NoteIn this chapter
Reading time. About 35 minutes.
You’ll need. Chapter 7 for commits and tags, Chapter 9 for the lockfile, and Chapter 10 for the container, in particular the canonical Dockerfile of Section 10.3. The paper inside the compendium is a Quarto file. This chapter shows only what a compendium needs from it; Chapter 23, in the second quarter, covers Quarto in full. The code calls every function with its namespace (purrr::walk(), renv::lockfile_read(), cli::hash_file_sha256()), so it needs no library() call.
You’ll be able to.
- Name the Five Pillars, what each pins, and the silent failure its absence causes, and say which a given repository lacks.
- Place each file of a project in the conventional layout, and protect the raw data with a checksum manifest.
- Assemble a compendium by hand from the
rrtoolslayout (or a Quarto project),renv, the canonical Dockerfile, and the manifest, with the paper written inside it. - Audit a compendium against the pillars with a short script, and verify it by rebuilding it from a fresh clone.
- Choose between assembling by hand and automating with
rrtools,workflowr, orzzcollab, for a given project. - Turn an analysis function into a documented, checked package function with
roxygen2andR CMD check, without any scaffolding tool.
Outline.
NoteSkip ahead?
If these answers come quickly, skip to the next chapter. The answers are in Section 11.15.
- What is a ‘research compendium’ as described by Marwick, Boettiger, and Mullen (2018) (Marwick et al., 2018), and how does an
rrtoolscompendium differ from a regular R package? - What are the Five Pillars of a reproducible research compendium? A project has a committed
renv.lockand a Dockerfile: which pillars does it still lack, and how would anyone notice? - When is a framework such as
rrtools,workflowr, orzzcollabworth adopting, and what does it leave for you to do?
11.1 What a research compendium is
A paper without its compendium is a description of an analysis. A compendium without a paper is code. Together they make a study artifact that does not depend on any one file or any one person. Gentleman and Temple Lang (2007) introduced the term. Marwick, Boettiger, and Mullen (2018) gave the working definition this book uses, which has three criteria:
| Criterion | What it requires | What fails without it |
|---|---|---|
| Single directory | Code, data, environment, and narrative together | A step lives elsewhere (a spreadsheet, a laptop), as the hand exclusion in the opening did |
| Computable | Another user can rerun the analysis with reasonable effort | The paper can be read but not checked |
| Self-describing | The layout follows a convention a stranger knows | Every file is a hunt, for the stranger and for you in eighteen months |
The argument for convention is practical. A directory organized to your own logic is navigable by you and by nobody else. ‘Nobody else’ includes the version of you that returns after eighteen months. A compendium that follows a recognized layout can be opened by a stranger who has seen one before. That reader will know where the paper is, where the raw data are, and which directory holds things that were derived rather than given. The specific convention matters much less than having one at all.
R packages already have a convention every R user knows (DESCRIPTION, R/, man/), which satisfies the third criterion and part of the first. What a package lacks is a study: data and a paper. The rrtools package (Marwick, 2018) supplies one convention that adds them, and Figure 11.2 shows the result.
flowchart TD
  C["Research compendium"]
  C --> P["<b>Package backbone</b><br/>DESCRIPTION, R/, man/<br/><i>convention and dependencies</i>"]
  C --> A["<b>analysis/</b><br/>data/, paper/, figures/<br/><i>the study itself</i>"]
  C --> D["<b>Dockerfile + renv.lock</b><br/><i>the environment</i>"]
  P --> N["<i>self-describing</i><br/>a stranger can navigate it"]
  A --> S["<i>single directory</i><br/>code, data, narrative together"]
  D --> R["<i>computable</i><br/>another user can re-run it"]
NoteCheck
Question. Why does rrtools reuse the R package structure instead of inventing a new layout?
Answer. There are three practical reasons. The package structure is the only widely recognized layout in the R ecosystem, so the compendium is navigable at no extra cost. The package also gives dependency declaration. DESCRIPTION lists what the code needs, and renv (Chapter 9) pins the versions. Finally, it gives function management, since helpers in R/ are documented, tested, and loadable into the analysis. The cost is a few package files that are not used as a package. There is no submission to CRAN (the Comprehensive R Archive Network) and no users importing it. That cost is small relative to the structural benefit.
11.2 Where files go
11.2.1 The layout
rrtools produces the layout below. Most compendium conventions differ from it only in names.
readmissions/
├── DESCRIPTION
├── NAMESPACE
├── R/                       # reusable functions
├── man/
├── analysis/
│   ├── data/
│   │   ├── raw_data/
│   │   └── derived_data/
│   ├── figures/
│   ├── paper/
│   │   ├── paper.qmd
│   │   └── references.bib
│   └── supplementary-materials/
├── Dockerfile
├── data-manifest.sha256
├── .github/
│   └── workflows/
├── README.qmd
├── README.md
└── readmissions.Rproj| Path | Holds | Commit it? |
|---|---|---|
R/ |
Reusable functions: cleaning helpers, plotting wrappers, model utilities, documented with roxygen | Yes |
analysis/data/raw_data/ |
The data exactly as received, never edited | If small and unrestricted; otherwise document the access path |
analysis/data/derived_data/ |
Everything the scripts produce from the raw data | Optional: commit when small and the analysis is archived |
analysis/paper/paper.qmd |
The manuscript, with the code that produces its numbers | Yes |
analysis/figures/ |
Figures the analysis writes | Usually not; the code that makes them is committed |
analysis/supplementary-materials/ |
Appendix tables, sensitivity analyses | Yes |
data-manifest.sha256 |
One checksum per raw file | Yes, always, even when the raw data cannot be committed |
README.qmd |
What the project is, how to build it in one command, where the paper and data are, how to cite it | Yes |
The README is the entry point, not the documentation. It says what the project is, how to rebuild it, and where things are. Long technical notes live elsewhere.
11.2.2 Raw data are read-only
Raw and derived data live in separate directories because raw data are evidence and derived data are a build product. Writing a cleaned table back over the input destroys the only copy of what you were given. Version control does not recover a file that was overwritten before it was ever committed. Treat raw_data/ as read-only, by convention if your file system will not enforce it. Then make the convention checkable by recording a checksum of every raw file when it arrives. The chunk below builds the layout above in a temporary directory and copies in two of the HF-HOME raw files.
comp <- file.path(tempdir(), "readmissions")
layout <- c("R", "analysis/data/raw_data", "analysis/data/derived_data",
            "analysis/paper", "analysis/figures")
purrr::walk(file.path(comp, layout), dir.create, recursive = TRUE,
            showWarnings = FALSE)

hf_dir <- file.path("..", "data", "raw_data", "hfhome")
raw_dir <- file.path(comp, "analysis", "data", "raw_data")
file.copy(file.path(hf_dir, c("randomization.csv", "outcomes.csv")),
          raw_dir, overwrite = TRUE)
#> [1] TRUE TRUE
The manifest has one line per file. Each line holds the file’s SHA-256 checksum (a 64-character fingerprint of its contents) and its path from the compendium root. This is the format the shasum command reads and writes. You can therefore create the manifest in R, and anyone can check it from a shell.
raw_files <- list.files(raw_dir, pattern = "\\.csv$")
sums <- vapply(file.path(raw_dir, raw_files), cli::hash_file_sha256,
               character(1))
writeLines(paste0(sums, "  ",
                  file.path("analysis", "data", "raw_data", raw_files)),
           file.path(comp, "data-manifest.sha256"))
readLines(file.path(comp, "data-manifest.sha256"))
#> [1] "8746dd3588f207193182c3499ae588c255e567d99d374ea5650da1e5f974f7c4  analysis/data/raw_data/outcomes.csv"
#> [2] "118b64fe01fd38f25777ee6731b78e9c8a1038781fa12bd4ac4fbe3c7d261e88  analysis/data/raw_data/randomization.csv"

check_raw <- function(root) {
  lines <- readLines(file.path(root, "data-manifest.sha256"))
  recorded <- setNames(sub("  .*$", "", lines),
                       sub("^\\S+  ", "", lines))
  current <- vapply(file.path(root, names(recorded)),
                    cli::hash_file_sha256, character(1))
  changed <- names(recorded)[unname(current) != recorded]
  if (length(changed) > 0) {
    stop("raw data changed since the manifest: ",
         paste(changed, collapse = ", "), call. = FALSE)
  }
  invisible(TRUE)
}
check_raw(comp)
From the compendium root, shasum -a 256 --check data-manifest.sha256 checks the same manifest from the shell. A checksum detects accidental change, which is the job here. It is not a defense against deliberate tampering, since whoever can edit the data can edit the manifest beside them.
WarningPitfall
A ‘quick fix’ saved over the raw export leaves no trace in the data. Exclude a few patients by hand and save the file in place. Every later run then reads the edited file as if it were what the site sent:
The analysis would have run, on 2,429 patients instead of 2,432, with no error. The manifest turns the change into an error. Exclusions belong in code, in derived_data/, where they are counted and reviewed.
NoteCheck
Question. Your cleaning script reads analysis/data/raw_data/visits.csv and produces a tidy analytic table. Where does the output go, and should it be committed?
Answer. It goes in analysis/data/derived_data/. Whether to commit it is a trade-off, not a rule. On the minus side, it is reproducible from the raw data and the script. Storing it duplicates information and adds a binary that changes on every run. On the plus side, it lets a reader check your numbers without installing your environment. It also fixes what the analysis actually used, which matters if the cleaning script is later corrected. The usual resolution is to commit derived data when it is small and the analysis is being archived, and to leave it untracked during development. What is not defensible is committing derived data and not the script that made it. That arrangement looks tidiest and explains least, and it is the one behind the opening’s stale dataset.
11.2.3 Exercises
- Assign each file from a messy project to the layout of Table 11.2:
helpers.R(three functions used by two scripts),crf_export_2025-06-01.csv(from the data center),analytic.rds(written byclean.R),fig2.png,notes.txt(a dated log of decisions),clean.R, andmanuscript.qmd.
NoteSolution
| File | Goes to | Why |
|---|---|---|
helpers.R |
R/ |
Reused by more than one script |
crf_export_2025-06-01.csv |
analysis/data/raw_data/ |
Received, not produced; add it to the manifest |
analytic.rds |
analysis/data/derived_data/ |
Produced by a script; regenerable |
fig2.png |
analysis/figures/ (usually untracked) |
Produced by code |
notes.txt |
Top level or analysis/ as a decision log |
Not data and not code; keep it with the project and in Git |
clean.R |
analysis/ (scripts) |
Study-specific code that turns raw into derived data |
manuscript.qmd |
analysis/paper/paper.qmd |
The manuscript |
The judgment calls are notes.txt, which fits no category and should not be forced into one, and clean.R, which some conventions put in analysis/scripts/. Either location works if a stranger can predict it.
11.3 The Five Pillars
The three criteria say what a compendium must achieve, and the layout says where its files go. The Five Pillars say what it must contain to achieve them. The preceding chapters each solved one layer of the reproducibility problem. Each left it to you to connect that layer to the others. A compendium layout does not come with a lockfile. A lockfile (Chapter 9) does not come with a container. A container (Chapter 10) does not know where your data came from. The Five Pillars are the checklist that says when the connections are complete. They are tool-neutral roles. The book uses the R tools for each, but every language has a tool for each role. The same five hold whether you assemble them by hand or let a framework do it. Table 11.3 states what each pins and what goes wrong without it.
| Pillar | Pins | In this book | Elsewhere | Without it | Check |
|---|---|---|---|---|---|
| 1. Dockerfile | Operating system, system libraries, the R build |
Dockerfile (Chapter 10) |
Apptainer definition, Nix | Packages restore onto a different R or BLAS (Basic Linear Algebra Subprograms), and the last digits of an estimate move | The base image’s R version equals the lockfile’s |
2. renv.lock
|
The exact version and source of every R package |
renv.lock (Chapter 9) |
uv.lock, conda environment.yml
|
A collaborator’s newer packages, or a changed default in one, change a number without an error |
renv::status() reports no issues |
3. .Rprofile
|
Activation of the project library at startup |
.Rprofile (Chapter 9) |
A virtual-environment activation script | R loads the global library instead, and the lockfile is silently bypassed |
.libPaths()[1] is inside renv/library where you render |
| 4. Source code | Every step, from raw data to every number |
R/ and analysis/ in Git (Chapter 7) |
Any version-controlled scripts | A hand step or an edited script is not in the history, or nobody can identify the version that ran | Committed to Git, and the submitted version tagged |
| 5. Data | The raw inputs, unchanged, or the documented way to get them |
analysis/data/raw_data/ with a checksum manifest |
A DOI’d deposit with access instructions | A stale derived file or a later extract gives a different answer from the same code | A committed checksum manifest verifies |
The opening’s three causes map onto pillars 2, 4, and 5. The remedy for each is a file: a lockfile, a script for every step, and raw data that the code reads and never writes. Some frameworks automate the pillars. zzcollab (Section 11.9) is one, and it scaffolds and audits all five.
The pillars are easier to remember as a stack than as a list. Each one captures a layer that the one above it takes for granted. Figure 11.3 shows that stack.
flowchart TD
  D["<b>5. Data</b><br/><i>raw and derived, or a documented path to them</i>"]
  S["<b>4. Source code</b><br/><i>the analysis, in R/ and analysis/</i>"]
  P["<b>3. .Rprofile</b><br/><i>activates the project library</i>"]
  L["<b>2. renv.lock</b><br/><i>every R package version</i>"]
  F["<b>1. Dockerfile</b><br/><i>operating system, system libraries, R build</i>"]
  F --> L --> P --> S --> D
Two of the pillars need more explanation than the table gives them. First, the renv.lock records the R version as well as every package, but it does not install R. The R installation comes from the Dockerfile, which is why the two must agree. Second, the data pillar does not require the data to be in the repository. Sensitive data often cannot live in the compendium. In that case the compendium holds a README documenting the access path, in the form Chapter 34 sets out. It also holds a manifest of checksums that lets anyone confirm they obtained the same files. The shared-drive variant of the opening was a data pillar with the README and without the manifest.
NoteCheck
Question. A project has a Dockerfile and a committed renv.lock, and its .Rprofile activates renv. Which pillars does a collaborator still have to take on trust?
Answer. Two. The source code is pinned only if it is committed and the version you reported is tagged. Otherwise the collaborator cannot know which commit produced the paper. The data are pinned only if they are in the repository or a manifest records their checksums. Otherwise a later extract produces a different answer from the same code, with nothing to say so. The environment pillars cannot detect either problem.
NoteCheck
Question. Your compendium has a renv.lock and a Dockerfile. A colleague argues that the lockfile is redundant, because the image already contains the packages. Is it?
Answer. No. The image contains the packages that were current when it was built. A rebuild months later installs whatever is current then, unless the lockfile pins them. The Dockerfile’s restore step reads the lockfile for exactly that reason. The pillars are a stack, not a menu. The Dockerfile pins what is beneath R, and the lockfile pins what is above it.
11.3.1 Exercises
- A repository contains
analysis.R,clean.R,data.csv(described in the README as ‘cleaned’),renv.lock, and a README that says ‘run analysis.R in RStudio’. Which pillars are present, which are missing, and what would a collaborator’s rerun be unable to establish?
NoteSolution
Present: package versions (renv.lock) and source code, assuming the repository is under Git. Missing: the environment beneath R (no Dockerfile, so R and system libraries are whatever the collaborator has), activation (no .Rprofile, so the lockfile is ignored unless she restores it by hand), and the raw data. The data pillar is the serious gap. data.csv is derived, so a rerun can check analysis.R against it but can never check clean.R. Any hand step between the raw export and data.csv is also invisible. Add the raw export (or its access path), make clean.R read it and write to derived_data/, and record a checksum manifest.
11.4 Assembling the compendium by hand
Assembling the pillars by hand takes about half an hour per project. Doing it once is the best way to understand what any framework that automates it is doing for you. Each step uses a tool from an earlier chapter. The commands below are display-only, because they create a project on your machine.
-
Layout and source code. Scaffold the compendium with
rrtools(Section 11.4.1) and put it under Git (Chapter 7):rrtools::use_compendium("~/research/hfhome") rrtools::use_analysis()git init -
Lockfile and
.Rprofile. Initializerenv, which writes both, install what the analysis uses, and snapshot (Chapter 9): Dockerfile. Copy the canonical Dockerfile from Section 10.3 to the project root, with its
.dockerignore, and set the base image’s tag to the R version inrenv.lock. Use it in place of the onerrtools::use_dockerfile()writes (Section 11.4.1).Data. Put the raw files in
analysis/data/raw_data/, or a README there that says how to obtain them, and commit a checksum manifest of the files (Section 11.2).-
Tag. Commit, and tag the commit you submit:
git tag -a v1.0-submission -m "Submitted to journal"
11.4.1 Scaffolding with rrtools
The calls below are display-only, because they create a project and open it as a new RStudio session:
# install
install.packages("remotes")
remotes::install_github("benmarwick/rrtools")

# create a new compendium
rrtools::use_compendium("~/research/readmissions")
# (this also runs usethis::create_package internally)

# add the analysis directories
rrtools::use_analysis()

# add a Dockerfile and, by default, a GitHub Actions
# workflow that renders the paper inside it
rrtools::use_dockerfile()

# add a README.qmd
rrtools::use_readme_qmd()
rrtools::use_dockerfile() writes its own Dockerfile, based on rocker/verse. This book replaces it with the canonical Dockerfile in Section 11.5. This chapter, Chapter 9, and Chapter 10 then describe one file rather than several.
11.4.2 Other conventions
rrtools is one convention among several. The right one depends on the project’s shape and the team’s habits:
| Convention | Shape | Use when |
|---|---|---|
rrtools |
R package plus analysis/
|
A paper with reusable R code; the default for a biostatistical paper |
| Quarto manuscript project | A Quarto project whose output is an article | A paper-first project without a package backbone |
| Quarto book | A Quarto project with chapters | Book-length output, such as this practicum |
A framework such as zzcollab (Section 11.9) |
Scaffolds all five pillars and audits them | You want the pillars generated and checked for you |
| The TIER Protocol (Teaching Integrity in Empirical Research) | A documented folder convention | Social-science collaborators who already use it |
| Your group’s template | Whatever the group agreed | Always, if one exists: consistency with colleagues beats any external default |
rrtools is a reasonable default once you have checked that no other row of the table fits the project better.
ImportantLLM prompt
Use a model to propose a layout for an existing project, and apply the moves yourself.
Context. Below is the output of
git ls-filesfor an R analysis project, and the compendium layout I want (the table of paths and contents). The working tree is clean and committed.Constraints. Propose only
git mvcommands. Do not move, rename, or edit anything underdata/raw/; raw files keep their names and contents, and are moved, if at all, only intoanalysis/data/raw_data/with a separate command I will run myself. Delete nothing. Do not edit file contents.Criteria. Every file is assigned exactly once. List the files that fit no category, with your reasoning, rather than forcing them into one, and list every script whose file paths will break after the moves.
Failure mode. A model assigns every file somewhere, confidently, including logs and exploratory notebooks that fit nowhere. It also proposes edits to paths inside scripts that silently change what they read. Raw files moved or renamed lose the link to their provenance. Check. After applying the moves, git status and git diff -M --name-status HEAD should show only renames (R100), with no modifications or deletions. Update the manifest’s paths to the new locations and rerun shasum -a 256 --check data-manifest.sha256, which should pass. A fresh render should produce the same numbers. The prompt sends file names, not data (Section 12.3).
11.4.3 The paper inside the compendium
analysis/paper/paper.qmd is the manuscript, written in Quarto: code chunks for the analyses, inline numbers, figure cross-references, and citations from references.bib. The file below is all a compendium needs; Chapter 23 explains each part.
---
title: "Effect of post-discharge home health visits on 30-day readmission"
author:
  - name: A. Author
  - name: B. Coauthor
format:
  pdf: default
  html: default
bibliography: references.bib
---

# Methods

We analyzed `{r} nrow(d)` patients from the institutional
EHR cohort. The primary outcome was 30-day all-cause
readmission and the exposure was receipt of a home-health
visit. We fit a multivariable logistic regression
adjusting for age, sex, baseline ejection fraction, and
discharge medications, in R [@rcore2024].

```{r}
#| label: fit-model
#| echo: false
fit <- glm(readmit ~ home_health + age + sex + ef + meds,
           family = binomial, data = d)
ci <- exp(confint.default(fit)["home_health", ])
```

The adjusted odds ratio for home-health-visit receipt
was `{r} round(exp(coef(fit)["home_health"]), 2)` (95% CI
`{{r}} round(ci[1], 2)` to `{r} round(ci[2], 2)`).
Every number in the methods and results comes from code, so a rerun on corrected data changes the prose with the tables. EHR here is the electronic health record. The example is an observational cohort, which is why the exposure is receipt of a visit and the estimate is adjusted.
For journal-specific formatting in Quarto, use a Quarto journal extension where one exists for your journal. The quarto-journals collection on GitHub includes, for example, a template for JASA (the Journal of the American Statistical Association):
quarto use template quarto-journals/jasaThe extension adds a format (here jasa-pdf) that you name under format: in paper.qmd. The older rticles package offers more journals, including Statistics in Medicine, Biometrics, and JASA (rticles::journals() lists them). However, its templates are R Markdown output formats for an .Rmd file rendered with rmarkdown::render(), not Quarto formats. They cannot be named in the format: key of a .qmd. Neither collection has a template for every medical journal (there is none for NEJM or JAMA, for instance). Most of those journals accept a plain PDF or Word manuscript at first submission.
TipVerification
Render the paper in a fresh session and read the warnings, which are where unresolved citations and cross-references surface:
quarto render analysis/paper/paper.qmd 2>&1 | grep -i warnIt should print nothing. A warning that a citation or a cross-reference cannot be resolved means the rendered paper shows a placeholder where a reference belongs.
11.4.4 A compendium with two gaps
The manifest is the step most projects skip. The chunk below assembles a small HF-HOME compendium in a temporary directory. It deliberately leaves out the manifest step and uses a Dockerfile copied from an older project. The audit in Section 11.7 then has something to find.
hf_dir <- file.path("..", "data", "raw_data", "hfhome")
comp <- file.path(tempdir(), "hfhome-compendium")
unlink(comp, recursive = TRUE)
raw <- file.path(comp, "analysis", "data", "raw_data")
dir.create(raw, recursive = TRUE)
dir.create(file.path(comp, "R"))
invisible(file.copy(
  file.path(hf_dir, c("randomization.csv", "outcomes.csv")), raw
))
writeLines(
  "derive_analysis_set <- function(rand, outc) merge(rand, outc)",
  file.path(comp, "R", "derive.R")
)
writeLines('source("renv/activate.R")', file.path(comp, ".Rprofile"))
writeLines(
  '{"R": {"Version": "4.4.0", "Repositories": []}, "Packages": {}}',
  file.path(comp, "renv.lock")
)
writeLines(c("FROM rocker/r-ver:4.3.1", "WORKDIR /work"),
           file.path(comp, "Dockerfile"))
invisible(system2("git", c("init", "-q", comp)))
list.files(comp, recursive = TRUE, all.files = TRUE,
           include.dirs = FALSE) |>
  grep(pattern = "^[.]git/", invert = TRUE, value = TRUE)
#> [1] ".Rprofile"
#> [2] "analysis/data/raw_data/outcomes.csv"
#> [3] "analysis/data/raw_data/randomization.csv"
#> [4] "Dockerfile"
#> [5] "R/derive.R"
#> [6] "renv.lock"
Every pillar has a file. Whether every pillar is pinned is a different question, and the listing cannot answer it.
WarningPitfall
An .Rprofile that never runs. R reads .Rprofile from the directory it starts in, then from your home directory. Suppose you render from a subdirectory (cd analysis/paper, or an RStudio project rooted there). The project’s .Rprofile at the root then never runs. There is no error and no message, and the analysis uses your global library while the lockfile says otherwise. This book ran into exactly this problem, because Quarto starts R in the directory being rendered. Its fix is a second .Rprofile in analysis/report/ that points renv at the project root. The check in Table 11.3 catches it: run .libPaths()[1] from the directory where you render.
NoteCheck
Question. Step 3 sets the Dockerfile’s base tag to the R version in renv.lock. What happens if the two disagree, and why is nothing likely to report it?
Answer. renv restores the recorded package versions onto whatever R the image supplies. The build usually succeeds, because most package versions install on a neighboring R, and the analysis runs. What changes is the layer beneath the packages (R itself, and the numerical libraries it links). Results can therefore differ in their last digits from the ones you reported, with no error anywhere.
11.5 Building and sharing
A compendium is built in one of three ways. You can render the paper in RStudio while writing. You can source the analysis scripts in order after devtools::load_all() to regenerate cached results. Or you can build the image, which is the only one of the three that reproduces the environment as well as the results. The book’s canonical Dockerfile, explained line by line in Section 10.3, sits at the compendium root:
# syntax=docker/dockerfile:1
FROM rocker/r-ver:4.4.0

ARG QUARTO_VERSION=1.6.40

RUN apt-get update \
  && apt-get install -y --no-install-recommends \
    ca-certificates curl \
    libcurl4-openssl-dev libssl-dev libxml2-dev libuv1-dev \
  && rm -rf /var/lib/apt/lists/*

# rocker/r-ver ships R but not the Quarto CLI
RUN arch="$(dpkg --print-architecture)" \
  && curl -fsSL -o /tmp/quarto.deb \
    "https://github.com/quarto-dev/quarto-cli/releases/download/v${QUARTO_VERSION}/quarto-${QUARTO_VERSION}-linux-${arch}.deb" \
  && dpkg -i /tmp/quarto.deb \
  && rm /tmp/quarto.deb

# outside /work, so a bind mount of the project cannot hide it
ENV RENV_PATHS_LIBRARY=/opt/renv/library

WORKDIR /work
COPY renv.lock .Rprofile ./
COPY renv/activate.R renv/activate.R
RUN R -q -e "renv::restore(prompt = FALSE)"

COPY . .

CMD ["quarto", "render", "analysis/paper/paper.qmd"]
From the compendium root (display-only):
docker build --platform linux/amd64 -t readmissions:v1.0 .
docker run --rm --platform linux/amd64 \
  -v "$(pwd)/analysis/paper:/work/analysis/paper" \
  readmissions:v1.0
The Dockerfile pins the R version, the system libraries, and (through renv.lock) the package versions. The rendered paper appears in analysis/paper/ on your machine. A reader with Docker can rebuild a very close copy of the environment that produced the paper. An exact copy needs the digest pin or archived image described in Chapter 10.
Deposition is treated in full in Chapter 34. Its shape affects how you organize the directory, so it is worth knowing now. GitHub (or your institution’s Git server) holds the working repository. An archive such as Zenodo holds a citable, DOI-bearing (digital object identifier) snapshot at submission, with the saved image. Restricted primary data go only where the data use agreement permits. That is often a controlled-access repository and sometimes nowhere, with the compendium documenting how to request them.
TipVerification
The test of a compendium is a rebuild by someone who is not you, from what is in the repository and nothing else. Simulate it (display-only):
git clone https://github.com/you/readmissions.git /tmp/fresh
cd /tmp/fresh
docker build --platform linux/amd64 -t readmissions:check .
docker run --rm --platform linux/amd64 \
  -v "$(pwd)/analysis/paper:/work/analysis/paper" readmissions:check
The paper must render, and its key numbers must match yours. A failure here names a file that lives only on your machine. That is the opening’s problem, found before your collaborator finds it.
NoteCheck
Question. Why is the fresh clone the right test, rather than rendering the paper again on your own machine?
Answer. Your machine has everything the repository forgot: the packages you installed, the derived files you never committed, the environment variables in your .Renviron. A rerun there passes whatever the compendium is missing. A fresh clone, built in a container, has only what the five pillars supply. It is therefore the first run that can fail for the reasons a collaborator’s would.
11.5.1 Exercises
- A colleague’s compendium renders on her laptop and fails in the fresh-clone check with
cannot open file 'analysis/data/derived_data/analytic.rds'. What is the likely cause, and what are the two acceptable fixes?
NoteSolution
The paper reads a derived file that exists on her disk and is not in the repository. Probably derived_data/ is listed in .gitignore and nothing in the build regenerates it. The first fix is to make the build produce it: the paper, or a script the Dockerfile’s command runs, calls the cleaning code on the raw data. This is the better fix, because it also tests the cleaning. The second fix is to commit the derived file together with the script that made it, which is acceptable for an archived analysis. Committing it without the script is the arrangement the layout Check warned against.
11.6 Worked example: a small compendium
Here we set up a simulation study as a compendium from scratch (display-only):
# scaffold; this opens the new compendium as its own
# RStudio project, and every later call runs in that
# session, whose working directory is the compendium
rrtools::use_compendium("~/research/sim2026")

rrtools::use_analysis()
rrtools::use_readme_qmd()

# the environment pillars: initialize renv, then replace
# rrtools's Dockerfile with the canonical one
renv::init()

# add the simulation function
usethis::use_r("simulate")
# (write R/simulate.R with a documented function)
devtools::document()

# add the paper
file.edit("analysis/paper/paper.qmd")
# (write the manuscript using simulate() from the package)

# render
quarto::quarto_render("analysis/paper/paper.qmd")

# version control
usethis::use_git()
usethis::use_github(private = TRUE)
Then snapshot, commit, and tag the milestone from the shell, in the compendium directory:
Rscript -e 'renv::snapshot()'
git add .
git commit -m "Initial compendium"
git tag -a v0.1-draft -m "Initial draft for PI review"
The compendium is now a self-contained directory. It holds package-style code and a paper that uses the code. A lockfile and a Dockerfile pin the environment, and there is a Git history with a tag at a meaningful milestone. The setup takes about thirty minutes.
TipVerification
Confirm that the pillars are committed and the tree is clean:
git ls-files Dockerfile renv.lock .Rprofile analysis/paper/paper.qmd
git status --short
git tag -l 'v0.1*'
The first command should list all four files. The second should print nothing, and the third should print v0.1-draft. Then run the fresh-clone check of Section 11.5 against the tag.
11.7 Auditing the pillars
A checklist you run by eye drifts. A checklist you run as code does not. The function below turns Table 11.3 into five assertions about a project directory. It uses only renv, cli, and base R, so it audits a compendium however it was assembled.
audit_pillars <- function(root) {
  path <- function(...) file.path(root, ...)
  lock_r <- if (file.exists(path("renv.lock"))) {
    renv::lockfile_read(path("renv.lock"))$R$Version
  } else {
    NA_character_
  }
  from <- if (file.exists(path("Dockerfile"))) {
    grep("^FROM ", readLines(path("Dockerfile")), value = TRUE)[1]
  } else {
    NA_character_
  }
  rprofile <- if (file.exists(path(".Rprofile"))) {
    readLines(path(".Rprofile"))
  } else {
    character(0)
  }
  code <- list.files(root, pattern = "[.](R|qmd|Rmd)$",
                     recursive = TRUE)
  manifest <- path("data-manifest.sha256")
  data_ok <- file.exists(manifest) && {
    m <- read.table(manifest, col.names = c("sha256", "file"))
    all(vapply(path(m$file), cli::hash_file_sha256, character(1)) ==
          m$sha256)
  }
  data.frame(
    pillar = c("Dockerfile", "renv.lock", ".Rprofile",
               "Source code", "Data"),
    check = c("base image tag equals the lockfile's R version",
              "lockfile present and readable",
              "activates renv",
              "analysis code present, under Git",
              "raw files match the checksum manifest"),
    ok = c(
      !is.na(from) && !is.na(lock_r) &&
        grepl(paste0(":", lock_r, "($|@)"), from),
      !is.na(lock_r),
      any(grepl("renv/activate.R", rprofile, fixed = TRUE)),
      length(code) > 0 && file.exists(path(".git")),
      data_ok
    )
  )
}

audit_pillars(comp)
#>        pillar                                          check    ok
#> 1  Dockerfile base image tag equals the lockfile's R version FALSE
#> 2   renv.lock                  lockfile present and readable  TRUE
#> 3   .Rprofile                                 activates renv  TRUE
#> 4 Source code               analysis code present, under Git  TRUE
#> 5        Data          raw files match the checksum manifest FALSE
Two pillars fail. The Dockerfile names R 4.3.1 while the lockfile records 4.4.0, and there is no manifest for the data. To fix both, set the base tag to the lockfile’s version and write the manifest.
lock_r <- renv::lockfile_read(file.path(comp, "renv.lock"))$R$Version
writeLines(c(paste0("FROM rocker/r-ver:", lock_r), "WORKDIR /work"),
           file.path(comp, "Dockerfile"))

data_files <- list.files(raw, full.names = TRUE)
writeLines(
  paste0(vapply(data_files, cli::hash_file_sha256, character(1)),
         "  ", file.path("analysis", "data", "raw_data",
                         basename(data_files))),
  file.path(comp, "data-manifest.sha256")
)

audit <- audit_pillars(comp)
audit
#>        pillar                                          check   ok
#> 1  Dockerfile base image tag equals the lockfile's R version TRUE
#> 2   renv.lock                  lockfile present and readable TRUE
#> 3   .Rprofile                                 activates renv TRUE
#> 4 Source code               analysis code present, under Git TRUE
#> 5        Data          raw files match the checksum manifest TRUE
TipVerification
Assert the audit rather than reading it, and confirm from a shell that the manifest is in the standard format (display-only; run it in the compendium’s root):
shasum -a 256 --check data-manifest.sha256The shell check prints OK beside each file. In your own project, run audit_pillars(".") from the root before every tag. Regenerate the manifest only when you deliberately receive new data, and commit it with the data change. For a project under Git, git ls-files Dockerfile renv.lock .Rprofile confirms that the files are committed, not merely present on your disk.
The audit is a structural check. It confirms that each pillar is present and consistent, and it finds what is missing. It cannot tell you that what is present works or that the analysis reproduces. That test is the rebuild from a fresh clone in Section 11.5. Build the image, restore the lockfile, run the analysis, and compare the results with the ones you reported.
ImportantLLM prompt
A model can map an unfamiliar project onto the pillars quickly. Give it the files that decide each pillar, not a description.
Context. Below are the output of
git ls-filesfor an R analysis project, theFROMline of its Dockerfile, theR$Versionfrom itsrenv.lock, and the full text of its.Rprofile.Constraints. Assess the Five Pillars (Dockerfile,
renv.lock,.Rprofile, source code, data) using only these inputs. Do not recommend a framework or a template. Do not propose moving or editing anything in the raw-data directory.Criteria. For each pillar: present, absent, or present but inert, with the line of input that shows it. For each gap, the smallest addition that closes it.
Failure mode. Models report a pillar as present because a file with the right name exists: an .Rprofile that never activates renv, a Dockerfile whose tag disagrees with the lockfile, a data README with no checksums. Or they recommend adopting a framework, which answers a different question. Check. Run audit_pillars() on the project and compare its ok column with the model’s verdicts. File names and configuration are structure; send no data files (Section 12.3).
NoteCheck
Question. The audit passes on your compendium. A month later a colleague edits one value in outcomes.csv to correct a data entry error and reruns the analysis. What does the audit report, and what should happen next?
Answer. The data pillar fails, because the file’s checksum no longer matches the manifest. That is the audit doing its job. The inputs changed, and now someone knows. Raw data are evidence, so the correction should not arrive as a hand edit to the file. It should arrive as a new extract with its provenance recorded. The manifest should be regenerated and committed with it, and the changed result explained.
11.7.1 Exercises
- In the toy compendium, change one outcome in
analysis/data/raw_data/outcomes.csvand rerun the audit. Which pillar fails?
NoteSolution
outcomes_path <- file.path(raw, "outcomes.csv")
lines <- readLines(outcomes_path)
lines[2] <- sub(",0,", ",1,", lines[2], fixed = TRUE)
writeLines(lines, outcomes_path)
audit_pillars(comp)[c("pillar", "ok")]
#>        pillar    ok
#> 1  Dockerfile  TRUE
#> 2   renv.lock  TRUE
#> 3   .Rprofile  TRUE
#> 4 Source code  TRUE
#> 5        Data FALSE
Only the data pillar fails. A one-character change to one patient is invisible to every other check, and to anyone reading the results. The manifest is what makes it detectable.
- Audit this book’s own repository with
audit_pillars(file.path("..", ".."))and explain each failure.
NoteSolution
Each FALSE is a pillar the book’s repository does not supply in the form the audit checks. A missing Dockerfile means the R version and system libraries are whatever the reader’s machine has. A missing data manifest means the reader cannot confirm the files match the ones the book was built from. Here, however, the HF-HOME files can be regenerated from their seeded script. A book that teaches the pillars is held to them too.
11.8 Choosing how much to automate
Assembling by hand gives you full control and costs half an hour per project. It is also exactly the kind of work that gets done slightly differently every time. That defeats the consistency it was supposed to produce. Alfred North Whitehead observed, in An Introduction to Mathematics (1911), that ‘civilization advances by extending the number of important operations which we can perform without thinking about them’. The tools below make the assembly one such operation. They automate parts of it. They differ in which pillars they supply and in how much of the layout they decide for you.
| Approach | Supplies | Leaves to you | Suits |
|---|---|---|---|
| By hand | Whatever you choose, as above | Every step, and its consistency across projects | Learning the pillars; a single paper |
rrtools (Marwick et al., 2018)
|
Package-style layout, a Dockerfile, a README | The lockfile, matching the Dockerfile to it, the data manifest | A paper with code, in the community-standard layout |
workflowr (Blischak et al., 2019)
|
A project website in which each results page records its Git commit and R session information | The lockfile, the container, the data manifest | An analysis that is shared as it develops, as a website |
zzcollab (Section 11.9) |
Layout, renv.lock, .Rprofile, Dockerfile, a Makefile, dependency checks |
The data manifest’s upkeep, and the choice of profile | A group producing many projects that should look alike |
How much infrastructure a project needs is a judgment. Too much on a small project is busywork, and too little on a large one is technical debt. A compendium is more than is needed for interactive exploration, a one-off script, or a teaching example whose point is the code. The same holds for a quick reproduction of someone else’s analysis, whose structure should control. A compendium is the right weight for a collaborative analysis passed between team members. It is also right for one that must survive months or years after its lead analyst has moved on, and for any analysis subject to the federal requirements of Chapter 34. A tool that makes the heavy path cheap shifts the answer toward more infrastructure at the margin. The decision is still yours.
Whichever path you take, write the group’s conventions down once. These include a preferred database client, a set of in-house packages, or a journal’s Quarto template. A template project or a shared lockfile is the place for them. Every new project then inherits them rather than listing them again.
NoteCheck
Question. A colleague argues that adopting a framework makes the pillar audit unnecessary, since the framework writes every file. What is wrong with the argument?
Answer. A framework writes the pillars once, at scaffolding time. The audit checks them now. Lockfiles drift as packages are installed, a Dockerfile’s base tag falls behind a lockfile snapshotted under a newer R, and data change after the manifest is written. Each failure in Table 11.3 can occur in a scaffolded project as easily as in a hand-built one.
11.8.1 Exercises
- For each project below, choose an approach from Table 11.5 and name the pillar you would check most often: (a) a one-off descriptive table for a clinician’s abstract; (b) a two-year trial analysis passed between three analysts; (c) a methods paper with a simulation study.
NoteSolution
- A script, with no compendium. If the abstract becomes a paper, promote it then. (b) A framework that makes every project in the group look alike,
zzcollabor a group template. The data pillar is the one to check most often, because extracts arrive throughout the trial. (c)rrtoolsor a hand-built compendium. The pillar to watch is the environment (Dockerfile and lockfile together), because simulation results depend on the random-number generator and numerical libraries. Other defensible answers exist. The reasoning should tie the approach to the project’s lifetime and the number of people who work on it.
11.9 Optional: automating the assembly with zzcollab
This section is optional. zzcollab is the author’s in-house framework (Appendix C). It is one way to automate the assembly, beside rrtools and workflowr, and nothing else in the book depends on it. It packages the ideas of rrtools, renv, and Docker into one command-line workflow. It trades control over the layout for speed of setup and uniformity across a group’s projects. It does not call rrtools. Instead it writes its own layout, modeled on the same compendium.1
1 Described as of the repository at github.com/rgt47/zzcollab in October 2026. Profiles, make targets, and the bundle schema have changed between versions; check the repository’s CHANGELOG.md and make help before relying on the details below.
11.9.1 The first-project walkthrough
The minimum zzcollab session (display-only):
mkdir hfhome-analysis
cd hfhome-analysis
zzc tidyverse             # scaffold (Five Pillars appear)
make r                    # enter R session inside Docker
                          # ... do analysis ...
make check-renv           # validate dependencies
make docker-render-qmd    # render the Quarto report
zzc tidyverse runs the framework’s scaffolding. After it completes, the directory contains a DESCRIPTION, R/, analysis/, and tests/ directories, a Quarto report at analysis/report/index.qmd, a minimal renv.lock, a Dockerfile on the rocker/tidyverse base, and a Makefile. It then offers to build the image. Git is a separate step (zzc git, or git init yourself). The generated Dockerfile pins the rocker base image by tag and, when Docker can resolve it, by digest (for example rocker/r-ver:4.6.0@sha256:...).
make r drops you into an interactive R session inside the container, with the project directory mounted, so files edited inside the container persist on the host. It does not build the image. If no image exists, it asks whether to run R on the host instead, and the default answer is No. An unbuilt image therefore stops you rather than silently substituting the host’s R. Build first with make docker-build if you declined at scaffolding time.
make check-renv runs zzrenvcheck::check_packages(auto_fix = TRUE, strict = TRUE) on the host. The first time it runs, it installs zzrenvcheck itself from the latest commit on GitHub, unpinned. It checks that the packages your code uses and the packages DESCRIPTION declares agree. Separately, it checks that DESCRIPTION and renv.lock agree. By default it does not follow indirect dependencies, so passing this check is not the same as renv::status() reporting no issues (Chapter 9). With auto_fix it edits DESCRIPTION and renv.lock to add what is missing. This can take two runs: the first pass adds a package to DESCRIPTION, and the lockfile update follows on the next. It is not a read-only audit. Use make check-renv-no-fix for a report that changes nothing. It does not build the Dockerfile or inspect .Rprofile or the data.
make docker-render-qmd runs quarto render analysis/report/index.qmd inside the container. (make docker-render renders an R Markdown report instead, analysis/report/report.Rmd by default.)
11.9.2 The project Makefile
Every zzcollab project gets a Makefile with many targets, and make help lists them. The ones used most are these:
zzcollab make targets.
| Target | Action |
|---|---|
make help |
List all targets |
make r |
Drop into R inside the project’s container |
make rstudio |
Launch RStudio Server (port 8787) |
make docker-render-qmd |
Render analysis/report/index.qmd in the container |
make check-renv |
Validate dependencies and add missing ones |
make check-renv-no-fix |
Validate dependencies without modifying files |
make snapshot |
Snapshot renv.lock in the container, then validate |
make docker-build |
Rebuild the image (use after adding packages) |
make hash-data |
Write a SHA-256 manifest of the raw-data directory |
make verify-data |
Check the raw data against that manifest |
make clean |
Remove package build artifacts |
make hash-data writes data-manifest.sha256 in the same shasum format as the manifest in Section 11.7, so audit_pillars() reads either. make docker-build rebuilds the image after you add packages or system dependencies. Until you do, make r silently uses the old image. make clean removes package build artifacts (*.tar.gz and *.Rcheck). It does not touch rendered reports or Quarto’s _freeze/ directory.
make rstudio is for browser-based work. Open http://localhost:8787 and log in as rstudio with the password rstudio, which the target prints. The target publishes port 8787 on all of your machine’s network interfaces. With that fixed password, use it only on a trusted network (see Chapter 10 for binding to 127.0.0.1 instead).
11.9.3 Choosing a profile
The command zzc <profile>, run inside an empty project directory, scaffolds a project using one of four profiles. A profile’s main job is to choose the rocker base image:
zzcollab profiles.
| Profile | Base image | Approximate size | Use |
|---|---|---|---|
minimal |
rocker/r-ver |
650 MB | Command-line work, continuous integration |
tidyverse |
rocker/tidyverse |
1.2 GB | Tidyverse data analysis |
rstudio |
rocker/rstudio |
980 MB | RStudio Server development |
publishing |
rocker/verse |
4.2 GB | Manuscripts that need LaTeX |
The tidyverse profile was formerly called analysis, and zzc analysis still works as a deprecated alias. There are no modeling or Shiny profiles. For those needs, the framework’s own advice is to start from one of the four and add packages inside the container. The profile is a substantive choice. A manuscript that must render to PDF needs LaTeX, which only the publishing profile’s base image has. On the other hand, a simple descriptive analysis in the publishing profile waits for a 4 GB image it does not need.
Modeling packages need no special profile. Install lme4 or survival inside the container, record them with make snapshot, and rebuild with make docker-build. When zzcollab generates the Dockerfile, it reads the packages that your code, DESCRIPTION, and renv.lock mention. It then adds the system libraries they need. A profile mismatch therefore costs a rebuild rather than a hand-edited apt-get line.
NoteCheck
Question. You are scaffolding a project that will fit a Cox proportional hazards model with survival::coxph() and a mixed-effects model with lme4::glmer(), then render the result as a PDF manuscript. Which profile?
Answer. publishing. The PDF manuscript is the one requirement a profile actually supplies, since publishing is the only profile whose base image includes LaTeX. The modeling packages are not a profile question at all. Install lme4 and survival inside the container, run make snapshot so that renv.lock and DESCRIPTION record them, and rebuild. Neither package needs an extra system library. survival is a recommended package that ships with R.
11.9.4 Bundles and extension
Profiles are defined in the repository’s templates/bundles.yaml, which has three sections. library_bundles name sets of system packages, package_bundles name sets of R packages, and profiles combine a base image with one bundle of each. There is no inherits key, and the quickstart command accepts only the four built-in profile names. A group that wants different defaults can add a profile entry in a fork and select it with zzc docker --profile <name>. However, the Dockerfile generator reads only the entry’s base_image. System libraries come from the packages the project uses. R packages are added inside the container and recorded with make snapshot. Group conventions therefore belong in a template project or a shared renv.lock, as for any other approach, not in a new profile.
11.9.5 Exercises
- Scaffold a
zzcollabproject in a scratch directory, copy the two HF-HOME files intoanalysis/data/raw_data/, runmake hash-data, and audit the result withaudit_pillars(). (This needs Docker and thezzccommand, and creates a project on your machine.)
NoteSolution
A complete scaffold passes every row except one. Until you commit, the source-code row’s Git check fails (zzc git or git init). If the Dockerfile row fails, compare its FROM line with the lockfile’s R$Version. The two were written at different times. The fix is to rebuild with make docker-build after a snapshot, not to edit the tag by hand. Run make check-renv-no-fix as well. Unlike make check-renv, it changes nothing.
11.10 Analysis code as a package, without zzcollab
zzc tidyverse writes a DESCRIPTION, an R/ directory, and a Dockerfile in one command. However, none of what makes that backbone useful is specific to zzcollab, or to rrtools, or to any framework. Consider a function documented with roxygen2, checked with R CMD check, and loadable by name instead of by source(). That is ordinary R package development, available to a repository that uses no framework at all. In this section we do that development by hand on one function from this chapter’s own examples. Adopting a scaffolding tool then becomes a question of convenience alone.
The function is the composite-outcome derivation that the rest of this book writes inline wherever it needs HF-HOME’s primary endpoint. The endpoint is 30-day readmission or death, with the outcome set to missing when the patient was never ascertained.
derive_composite_outcome <- function(outcomes) {
  outcomes |>
    dplyr::mutate(
      composite_30d = dplyr::if_else(ascertained,
                                     as.integer(event_30d),
                                     NA_integer_)
    )
}

outcomes <- readr::read_csv(
  file.path(hf_dir, "outcomes.csv"),
  col_types = readr::cols(patient_id = "c", .default = "?")
)
composite <- derive_composite_outcome(outcomes)
c(events = sum(composite$composite_30d, na.rm = TRUE),
  unascertained = sum(is.na(composite$composite_30d)))
#>        events unascertained
#>           508           163
Written this way, in a script, the function has three problems. It is reused by copying it (and silently diverging) into every script that needs it. It is documented only by whatever comment sits above it. And nothing checks that its argument or return value still match what a caller assumes six months later. Turning it into a package function fixes all three problems.
11.10.1 A minimal DESCRIPTION by hand
A package needs a DESCRIPTION file at its root. usethis and rrtools write one for you, but the file itself is nine lines of plain text, no different from one you type:
Package: hfhome
Title: Analysis Functions for the HF-HOME Trial
Version: 0.1.0
Authors@R: person("A", "Author", email = "a@example.org",
    role = c("aut", "cre"))
Description: Derivation and summary functions for the HF-HOME
    home-health trial analysis.
License: MIT + file LICENSE
Imports: dplyr
Encoding: UTF-8
Imports: is the field that matters most and is easiest to let drift. Every package a function in R/ calls with :: belongs here, and R CMD check (below) is what notices when one is missing.
11.10.2 Documenting with roxygen2
roxygen2 (Wickham, Danenberg, et al., 2024) turns a comment block directly above a function into its help page. The documentation stays with the code, in the file a reader already has open, instead of in a separate .Rd file that drifts out of sync. The block below would sit above derive_composite_outcome() in R/derive.R. It is display-only, because it edits a package source tree that does not exist on this machine:
#' Derive the HF-HOME composite outcome
#'
#' Sets the 30-day composite outcome (readmission or death) to
#' missing for patients whose outcome was never ascertained.
#'
#' @param outcomes A data frame with logical column `ascertained`
#'   and integer column `event_30d`.
#' @return `outcomes` with an added integer column `composite_30d`.
#' @examples
#' derive_composite_outcome(
#'   data.frame(ascertained = c(TRUE, FALSE), event_30d = c(1, 0))
#' )
#' @export
derive_composite_outcome <- function(outcomes) {
  outcomes |>
    dplyr::mutate(
      composite_30d = dplyr::if_else(ascertained,
                                     as.integer(event_30d),
                                     NA_integer_)
    )
}
Running devtools::document() reads every such block in R/. It writes man/derive_composite_outcome.Rd and the export() lines in NAMESPACE, and nobody edits either file directly (display-only):
devtools::document()
#> Writing NAMESPACE
#> Writing derive_composite_outcome.Rd
?derive_composite_outcome now works from any script that loads the package. The @examples block is code that can be run (and, in R CMD check, is run). A function whose documented @param no longer matches its signature is caught by the next step. A reader no longer has to discover the mismatch by trial and error.
11.10.3 Checking the package
R CMD check, run through devtools::check(), gives what roxygen2 comments alone cannot. It runs a battery of structural tests against the whole package, not just the one function you are looking at. The call is display-only, because it requires the package tree, which is not installed in this environment:
devtools::check()
#> ── R CMD check results ──────────────────────── hfhome 0.1.0 ────
#> Duration: 4.1s
#>
#> ❯ checking Rd \usage sections ... WARNING
#>   Argument items with no description in Rd object
#>   'derive_composite_outcome':
#>     'outcomes'
#>
#> 0 errors ✔ | 1 warning ✖ | 0 notes ✔
The warning above is deliberately left in to show what the check is for. It would have caught a @param line typed for the wrong argument name, which no amount of careful reading of the function body would catch. R CMD check also verifies that every package named after :: in R/ is declared in Imports: and that the examples run without error. It verifies that the NAMESPACE matches what roxygen2 wrote, and that the package installs cleanly in a fresh session. It is the same check CRAN runs on every submission. It is available to any package whether or not the package is ever submitted.
11.10.4 Optional: a browsable site with pkgdown
pkgdown (Wickham, Hesselberth, et al., 2024) renders every man/*.Rd page, along with the README, into a static website. The site is worth the one extra command when more than one person reads the functions (display-only):
pkgdown::build_site()
# or, to publish it automatically on every push:
usethis::use_pkgdown_github_pages()
For a one-author analysis this is usually not worth the setup. Consider instead a package that a team imports across several studies. A site can be linked in a chat message, which ?derive_composite_outcome cannot, and that is often what gets the documentation actually read.
Table 11.8 lines up what each layer costs against what it buys, continuing the comparison of Table 11.5.
| Step | By hand | Automated by rrtools / zzcollab
|
|---|---|---|
DESCRIPTION fields |
Typed once, about five minutes | Scaffolded with placeholders you still edit |
roxygen2 comment content |
Always yours to write | Never automated; no tool knows what a function does |
NAMESPACE and man/*.Rd
|
devtools::document(), one command either way |
Same command; not framework-specific |
R CMD check |
devtools::check(), one command either way |
Same command; not framework-specific |
pkgdown site |
pkgdown::build_site(), one command either way |
Same command; not framework-specific |
| Deciding to package the code at all | Your judgment | Your judgment; no framework makes this call |
The practical reading of the table is that rrtools and zzcollab save you the DESCRIPTION boilerplate and the decision about where files go, and nothing more. The work that makes a package worth having is writing the documentation and reading what the check reports. That work is the same with or without them. It is also the work most worth learning by hand once, as Section 11.4 argued for the pillars generally.
NoteCheck
Question. A colleague says there is no point documenting derive_composite_outcome() with roxygen2 unless the package is going on CRAN. Is that right?
Answer. No. roxygen2 and R CMD check are useful to any package, submitted anywhere or nowhere. CRAN simply runs the same check on what it receives. An in-house package that only two analysts ever install still benefits in three ways. The help page ?derive_composite_outcome works, and the check catches a @param that drifted from the signature. The examples block also runs as a test every time devtools::check() runs. CRAN submission adds a few more checks (URLs, spelling, package size). It does not add the value of documenting and checking in the first place.
11.10.5 Exercises
- Add a second function to the toy package above,
readmission_rate(composite), that returns the proportion of non-missingcomposite_30dvalues equal to 1. Write itsroxygen2block, including an@examplesline that would run underR CMD check, and say whichImports:entry, if any, it adds toDESCRIPTION.
NoteSolution
readmission_rate <- function(composite) {
  mean(composite == 1, na.rm = TRUE)
}
readmission_rate(composite$composite_30d)
#> [1] 0.2238872
#' Readmission or death rate among ascertained patients
#'
#' @param composite An integer vector of composite-outcome values,
#' as returned by [derive_composite_outcome()].
#' @return A single proportion between 0 and 1.
#' @examples
#' readmission_rate(c(1, 0, 0, NA))
#' @export
readmission_rate <- function(composite) {
mean(composite == 1, na.rm = TRUE)
}It adds nothing to Imports:. mean() and the comparison operator are base R, and the function never calls another package with ::. The example line uses a vector with a missing value on purpose. The check then exercises the same na.rm = TRUE branch that the real data uses.
11.11 Rules of thumb
- Habit 1: the compendium is the unit. Code, data, environment, and paper travel together in one directory with a convention a stranger knows. Audit all five pillars, not the ones a tool happens to write. Tag what you submit, because the fresh clone of that tag is the test.
-
Habit 2: raw data are evidence; derived data are a build product. Never write to
raw_data/. Commit a checksum manifest and change it only when new data arrive deliberately. Regenerate everything else from code. - Habit 4: pin the environment. The lockfile and the Dockerfile pin different layers, and they must agree on the R version.
11.12 Cumulative practice
-
Cumulative (uses Chapter 7, Chapter 9, and Chapter 10; the paper needs only the Quarto shown in Section 11.4.3). Assemble by hand a compendium for a small HF-HOME analysis: the
rrtoolslayout, withrandomization.csvandoutcomes.csvinanalysis/data/raw_data/and a checksum manifest; apaper.qmdthat reports the 30-day event proportion in each arm with inline code;renvwith a snapshot; and the canonical Dockerfile with its tag set from the lockfile. Commit and tagv0.1. Runaudit_pillars()until every row passes, then build the image and render the paper inside it from a fresh clone. -
On your own work (no key). Convert a ‘scripts and data’ project of your own into a compendium, documenting the location of every file and the reason for it. Audit it with
audit_pillars(), record for each failing pillar what it would take to close it and whether you think it is worth it, and record what the fresh-clone check found the first time you ran it.
NoteSolution
- The paper’s numbers come from the raw files, never typed. A minimal computing chunk:
rand <- read.csv(file.path(raw_dir, "randomization.csv"),
                 colClasses = c(patient_id = "character"))
outc <- read.csv(file.path(hf_dir, "outcomes.csv"),
                 colClasses = c(patient_id = "character"))
hf <- merge(rand[c("patient_id", "arm")],
            outc[c("patient_id", "event_30d")], by = "patient_id")
stopifnot(nrow(hf) == nrow(rand))
round(100 * tapply(hf$event_30d, hf$arm, mean, na.rm = TRUE), 1)
#> Home health  Usual care
#>        21.1        23.7
The chunk reads outcomes.csv from the HF-HOME directory, because the Pitfall in Section 11.2 edited the toy compendium’s copy. In your compendium, both files come from raw_data/, and check_raw() runs first. If the audit’s Dockerfile row fails, the base tag and the lockfile’s R version disagree. Set the tag from renv::lockfile_read("renv.lock")$R$Version. A passing audit is still a structural check. The fresh-clone render is the test.
11.13 Cheat sheet
| Task | Command or file | Guards against |
|---|---|---|
| Scaffold a compendium |
rrtools::use_compendium(), use_analysis()
|
An improvised layout |
| Pin what is beneath R | The canonical Dockerfile (Section 10.3); base tag equals renv::lockfile_read("renv.lock")$R$Version
|
A different R or system library |
| Pin the packages |
renv::init(), renv::snapshot(); check with renv::status()
|
Newer packages on a collaborator’s machine |
| Activate the project library |
.Rprofile, written by renv::init(); check .libPaths()[1] from the render directory |
A lockfile silently bypassed |
| Protect raw data |
data-manifest.sha256, from cli::hash_file_sha256() or make hash-data; shasum -a 256 --check data-manifest.sha256
|
Edits saved over the raw export; a later extract |
| Audit the pillars |
audit_pillars("."); git ls-files
|
A pillar missing, inert, or not committed |
| Render the paper | quarto render analysis/paper/paper.qmd |
Typed numbers |
| Use a journal format | quarto use template quarto-journals/<journal> |
Reformatting by hand |
| Test the compendium | Fresh clone, docker build, docker run
|
Files that live only on your machine |
| Mark a milestone | git tag -a v1.0-submission |
Not knowing what was submitted |
11.14 Further reading
- (Marwick et al., 2018), the paper that defines the research compendium as this chapter uses it, and whose framing every approach in the chapter inherits.
-
(Marwick, 2018), the
rrtoolspackage and its documentation. -
(Harrell, 2025), the closest peer treatment of what goes in the compendium’s
analysis/directory once it exists. -
(Wickham & Bryan, 2023), the
R Packagesbook, forroxygen2documentation,R CMD check, and publishing apkgdownsite in full.
11.15 Prerequisites answers
- A research compendium is a directory tree that bundles a study’s code, data, and narrative in one place, with a standardized layout. The reader can rerun the analyses and regenerate the paper with a single command. Marwick et al.
- argue that the compendium is the appropriate unit of reproducible research in R. An
rrtoolscompendium has three components: an R package backbone (DESCRIPTION,R/), which gives dependency declaration (Imports:); ananalysis/directory for the data and the paper, which holds the study; and a Dockerfile which, withrenv.lock, gives environment reproducibility. A regular R package exports functions for reuse by others and has no data or narrative. The compendium repurposes the package structure as infrastructure, not for distribution on CRAN.
- argue that the compendium is the appropriate unit of reproducible research in R. An
- The Five Pillars are: (1) a Dockerfile (captures the operating system and system libraries), (2) an
renv.lock(captures R package versions), (3) an.Rprofile(activates renv and sets project-local R options), (4) source code (the actual analysis), and (5) data (raw and processed, or a documented access path when data cannot be shared). Each pillar captures a layer that the others do not, and removing any one leaves the analysis unreproducible. A project with only a committedrenv.lockand a Dockerfile still has to pin the source code and the data (and, if it has no.Rprofile, its activation). The code is pinned when it is committed and the reported version tagged; the data, when the files are in the repository or a committed checksum manifest records them. Nobody notices their absence until a rerun gives a different answer, which is why the audit in Section 11.7 checks for them explicitly. - A framework is worth adopting when many projects should look alike or the setup will be repeated often. For a single paper, assembling by hand or with
rrtoolsis enough. Every framework writes the pillars once. Keeping them consistent afterwards (lockfile, Dockerfile tag, data manifest) is still yours, and the audit is how you check it.zzcollabwrapsrenvand Docker and followsrrtools’s layout without calling it.