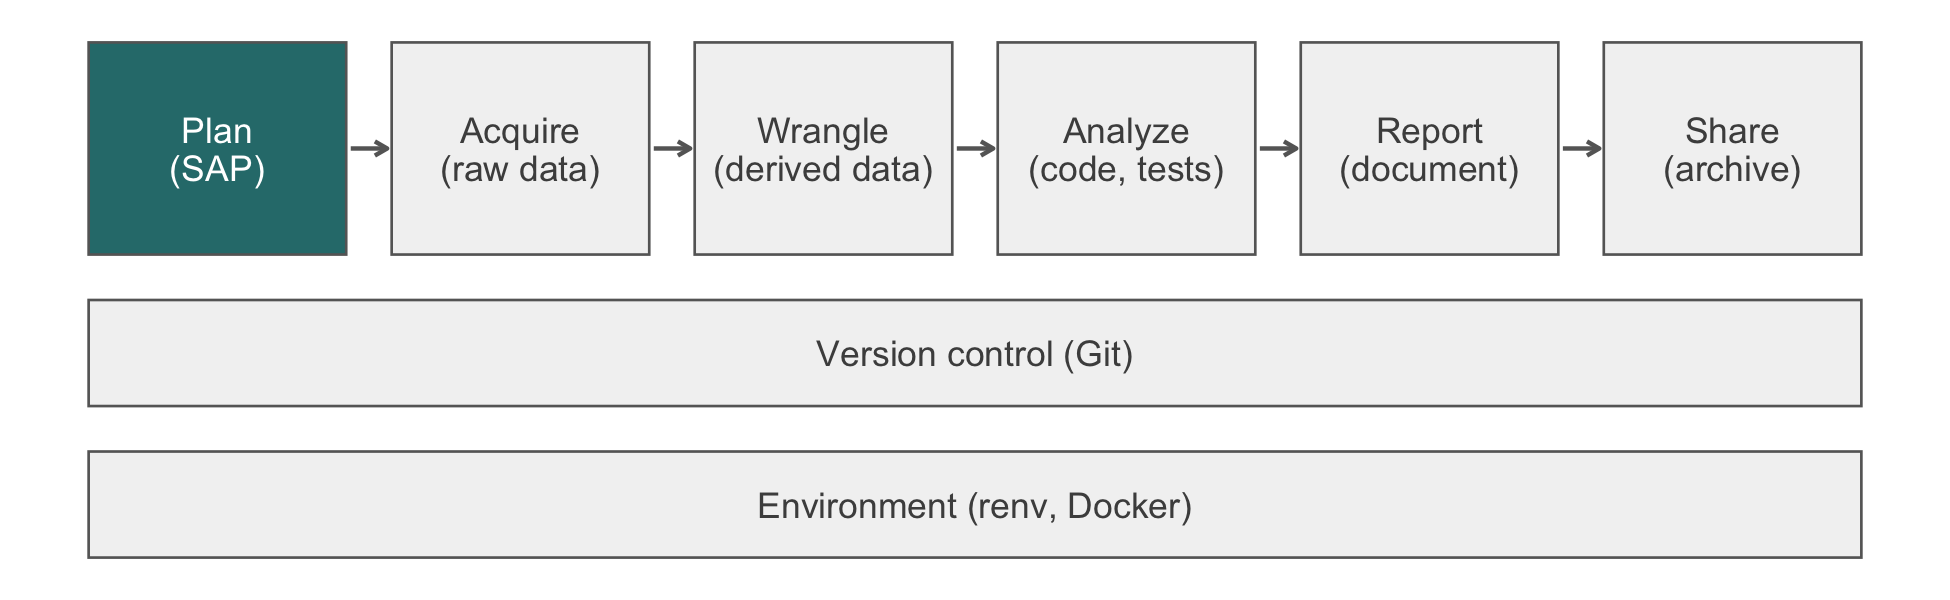
2 Why Reproducible Research
In 2006 a group at Duke University reported that gene-expression signatures derived from cancer cell lines could predict which patients would respond to which chemotherapy. Within a few years three clinical trials were using those signatures to choose patients’ treatment. Two biostatisticians at the MD Anderson Cancer Center, Keith Baggerly and Kevin Coombes, tried to reproduce the analyses from the published data and could not. When they reconstructed what must have been done, they found gene lists offset by one row and the labels of sensitive and resistant cell lines reversed (Baggerly & Coombes, 2009). None of these errors stopped any code from running, and each produced a signature that looked like a finding. The trials were halted in 2010 and the papers retracted (Institute of Medicine, 2012). Peer review did not expose the errors. Months of forensic reconstruction did, and a reproducible analysis would have made that work unnecessary.
An article about computational science in a scientific publication is not the scholarship itself, it is merely advertising of the scholarship. The actual scholarship is the complete software development environment and the complete set of instructions which generated the figures.
Jonathan B. Buckheit and David L. Donoho, WaveLab and Reproducible Research (1995)
NoteIn this chapter
Reading time. About 25 minutes.
You’ll need. No earlier chapter. The numbered habits the chapter cites are listed in Section 1.6. The one executed example reads a file from the book’s running study with base R, so it needs no library() call.
You’ll be able to.
- Classify a reanalysis as a test of methods, results, or inferential reproducibility.
- Name the three legs of a reproducible analysis and the tool that records each.
- Find the common reproducibility failures in a script and name the check that makes each one loud.
- State the cost-benefit case for reproducibility to a skeptical principal investigator (PI) in terms of events from your own work.
Outline.
NoteSkip ahead?
If these answers come quickly, skip to the next chapter. The answers are in Section 2.11.
- What does ‘reproducible’ mean in the context of a statistical analysis, and how is it different from ‘replicable’?
- What three artifacts must you share to make an analysis fully reproducible?
- Why is a reproducible analysis not necessarily a correct analysis? Give an example where the two diverge.
2.1 What ‘reproducible’ means
Reproducibility is the lowest bar a scientific analysis must clear. It says nothing about whether the analysis is correct, important, or even sensible. It says only that a second analyst, given the same inputs, can obtain the same outputs. Published analyses nonetheless fail this bar often, when someone outside the original team tries to rerun them from the materials provided.
The terms in this space are slippery. The most useful taxonomy is that of Goodman, Fanelli, and Ioannidis (2016), which distinguishes three kinds by what is held fixed (Table 2.1).
| Kind | Held fixed | Allowed to vary | Example | Nature of the problem |
|---|---|---|---|---|
| Methods (computational) | Data and code | Machine, operator | A colleague reruns your script on your data and gets your hazard ratio | Software engineering |
| Results (replicability) | Question and methods | The data: a new sample from the same population | A second trial at other sites finds a similar effect | Sampling |
| Inferential | The evidence: a reanalysis of the same data, or a replication | The analyst’s choices and interpretation | Two teams with the same trial data disagree on whether the effect is clinically meaningful | Judgment |
The kinds are progressively harder to secure. Inferential reproducibility is the broadest. Two analysts can share the data and the code and still reach different conclusions. They may have chosen different exclusions, models, or thresholds of clinical importance, or weighed the same estimate against different prior evidence. The National Academies of Sciences, Engineering, and Medicine (NASEM) report on the subject (National Academies of Sciences, Engineering, and Medicine, 2019) uses a simpler vocabulary for the first two rows. In that report, reproducibility means consistent results from the same data, code, and conditions of analysis. Replicability means consistent results from a new study that collected its own data. This book uses the NASEM words.
This book is about methods reproducibility. Without it the harder kinds are out of reach: if you cannot reproduce your own analysis, you cannot tell whether a discrepancy between yours and a colleague’s is a real disagreement or a bug.
2.1.1 Exercises
- Classify each scenario by the kind of reproducibility it tests.
- A reviewer runs your compendium in a container and obtains your Table 2. (b) A team in another country repeats your home-visit trial and finds a smaller effect. (c) A second statistician reanalyzes your trial data with a per-protocol population and concludes that the intervention is not worthwhile.
NoteSolution
- Methods: same data and code, different machine and operator.
- Results, which NASEM calls replicability: new data from a new sample. (c) Inferential: the same evidence, analyzed under different choices and judged by a different standard. Scenario
- can happen with a perfectly reproducible analysis.
NoteCheck
Question. Your reanalysis of a colleague’s published data gives a different odds ratio. Before arguing about whose model is better, what must you establish, and why?
Answer. That you can reproduce their number from their data and code (methods reproducibility). Until you can, the difference may be a bug, a different version of a package, or a different input file, and an argument about models would be an argument about noise. Once their number is reproduced, the remaining difference is a disagreement about choices, which is the inferential kind and is worth having.
2.2 Reproducibility cases
Two cases show what an irreproducible analysis costs and what finding its errors requires (Table 2.2).
The Duke case opened this chapter. Its lesson, in Baggerly and Coombes’s own summary, is that the most common errors are simple, such as row or column offsets, and that the simplest errors are the common ones (Baggerly & Coombes, 2009). The second case comes from economics. In 2010 Carmen Reinhart and Kenneth Rogoff reported that countries with public debt above 90 percent of gross domestic product (GDP) had sharply lower growth. The result was cited widely in arguments for austerity. Thomas Herndon, a graduate student at the University of Massachusetts Amherst, could not reproduce it for a class assignment. He and his professors then obtained the authors’ spreadsheet. In it they found a formula whose range omitted five countries, the selective exclusion of available years, and an unconventional weighting of the country averages. Corrected, average growth above the threshold was 2.2 percent, not the published -0.1 percent (Herndon et al., 2014). The spreadsheet error is the part most people remember. However, most of the gap came from analyst choices that were invisible until someone had the file.
| Case | What went wrong | How it was found | What would have made it loud |
|---|---|---|---|
| Duke genomics (2006 to 2010) | Gene lists offset by one row; sensitive and resistant labels reversed | Two outside statisticians reconstructed the analysis from published data | Released code and data; an assertion that sample labels match their source |
| Reinhart and Rogoff (2010 to 2013) | A formula range omitted five countries; years excluded; unusual weighting | A graduate student asked for the spreadsheet | Code in a script rather than cell formulas; a count of the countries entering each average |
Cases like these led Congress to direct the National Science Foundation to commission the NASEM report (National Academies of Sciences, Engineering, and Medicine, 2019). Its central recommendation on computational work is that researchers report the data, code, and computational environment behind a published result. The report should be clear enough for others to repeat the analysis. That is the compendium of Section 2.3.
In both cases the code ran and the output looked like a result. The error surfaced only when an outsider rebuilt the analysis, at great cost. Care caught neither error; a check that runs every time could have caught both. The book calls this idea make silent failures loud, and every tool in the chapters that follow is a way of doing it. The numbered habits that put the idea into practice are listed in Section 1.6; later chapters cite them by number.
2.2.1 Exercises
- A data frame
growthshould contain one row per country-year for 20 advanced economies. Write the assertion that would have made the omitted-countries error loud before any average was computed. Test it on the planted subset below.
growth <- data.frame(
  country = rep(sprintf('Country %02d', 1:20), each = 3),
  year    = rep(2007:2009, times = 20)
)
subset_used <- growth[growth$country > 'Country 05', ]
NoteSolution
The first assertion passes on the full data. The second stops, because the subset holds only 15 countries: the five that sort first are missing, exactly as a spreadsheet range that starts too low would drop them. The count is a structural check, and it catches only what it counts; it would not have caught the weighting choice, which is a matter of judgment for the methods section.
NoteCheck
Question. In both cases the error was found by someone outside the team. Why is that the expensive way to find it?
Answer. Because an outsider has to reconstruct the analysis before checking it, and without code and data the reconstruction is most of the work: months in the Duke case. By the time the error surfaces, results have been published, cited, and in the Duke case used to treat patients. A check inside the analysis runs on every build, at no marginal cost, before anything leaves the team.
2.3 The anatomy of a reproducible analysis
Three things must travel together for an analysis to be methods-reproducible, shown in Figure 2.2. If any one of the three is missing, the analysis cannot be rerun. In this sense the three are like the legs of a stool.
flowchart TD
  R["Reproducible<br/>analysis"] --> C["Code<br/><i>every step<br/>executable</i>"]
  R --> D["Data<br/><i>raw inputs,<br/>versioned</i>"]
  R --> E["Environment<br/><i>packages, R<br/>version, OS</i>"]
Code. Every step from raw input to final output, as executable code. No ‘I opened the file in Excel and sorted by date.’ No ‘I copied the column to a new sheet.’ Every transformation must be in the script.
Data. Either the actual data, or a precise description of how to obtain it. For protected health data, the description includes the access procedure (a data-use agreement, an institutional review board approval, a specific download location). For public data, include the data.
Environment. The R version, every package version, the operating system (OS), and system dependencies such as LaTeX or GDAL (the Geospatial Data Abstraction Library). Without this, the same code on the same data on a different machine can produce different results.
| Missing leg | What you have | What happens |
|---|---|---|
| Data | Code and environment | The analysis cannot run |
| Code | Data and environment | Nobody can tell what was done |
| Environment | Code and data | It works on your machine, and differs or fails on others |
The minimum reproducible compendium (Marwick et al., 2018) is exactly this: a directory containing code, data, and a declared environment, structured as an R package or similar artifact (Section 11.1).
2.3.1 Where judgment enters
Tools such as renv, Docker, and Quarto make the software part of reproducibility easy. The workflow part (which steps to script, what counts as a data file, when to commit) is harder, and it is where your judgment matters.
-
What goes in the script, and what goes in the README.
library(dplyr)belongs in the script. ‘Download the file from the secure portal’ belongs in the README. The boundary is whether the step can be automated; if it cannot, document it. - Which decisions to record. When you exclude observations with systolic blood pressure above 250 mmHg as implausible, the decision belongs in the script as a filter, with the threshold and a comment saying why. ‘Remove implausible BP values’ without a threshold is not reproducible.
- When to break the chain deliberately. Some steps are irreducibly manual: results from a web tool, images labeled by hand, a table transcribed from a paper. Document them in the README and treat their output as raw input to the reproducible chain. Do not pretend they were automated.
2.3.2 Exercises
- For each item, name the leg it belongs to and where you would record it: (a) you removed three participants whose consent was withdrawn; (b) the data arrive from a secure portal after a data-use agreement is signed; (c) the report needs a LaTeX installation; (d) the analysis used
survival3.7-0.
NoteSolution
| Item | Leg | Where it is recorded |
|---|---|---|
| (a) Consent withdrawals | Code | A filter in the script on a documented list of IDs, never a hand edit of the file |
| (b) Secure portal | Data | The README: the access procedure, the agreement, the file names and checksums |
| (c) LaTeX | Environment | The Dockerfile (Chapter 10) |
(d) survival version |
Environment |
renv.lock (Chapter 9) |
Item (a) is the one most often done by hand. The list of withdrawn IDs is itself raw input; the removal is code.
NoteCheck
Question. A colleague sends a script and a lockfile and says the data are ‘on the shared drive’. Which leg is missing, and what is the symptom when someone tries to rerun it in a year?
Answer. Data. A path on a shared drive is not a description of how to obtain the data: the file may have been overwritten, moved, or edited in place. The symptom is either an error (the file is gone) or, worse, a different number from a file with the same name and different contents. A checksum recorded beside the access procedure distinguishes the two.
2.4 How analyses fail
The failures that make an analysis irreproducible are almost never fraud, and rarely even carelessness in any sense the analyst would recognize at the time. A package was updated between the analysis and the revision. A file was renamed. A step was done by hand on a Thursday afternoon and never written down, because on that Thursday it was obvious. Each is trivial and invisible on its own. Together they make an analysis irreproducible six months later, usually to the surprise of the person who wrote it. Vigilance does not scale and cannot be audited. The remedy is a small number of structural habits that make these failures impossible.
1 lists the common failures, each with the check that makes it loud and the chapter that teaches the tool.
| Failure | How it shows up | What makes it loud | Taught in |
|---|---|---|---|
| Missing random seed | A bootstrap interval, imputation, or simulation differs on every run, usually in a late decimal place |
set.seed() in the script; two runs compared with identical()
|
This chapter |
| Unpinned package versions | The same code returns a different number after an upgrade, perhaps with a deprecation warning nobody reads | A lockfile and renv::status()
|
Chapter 9 |
| Undocumented manual steps | The reported numbers cannot be regenerated from the raw data | A script for every step; raw data kept read-only | Section 11.1, Chapter 13 |
| Hidden global state | The script runs only in your session, which holds objects or options it silently uses | A fresh session for every run (Rscript, or a render in a clean process) |
Chapter 6 |
| ‘Works on my machine’ | A system library, font, or LaTeX version exists on your machine and not on others’ | A container that pins everything beneath R | Chapter 10 |
| Stale intermediate | A figure is built from a file that was never rebuilt after the cleaning script changed | A dependency graph that rebuilds what is out of date | Chapter 24 |
Hidden global state deserves a warning of its own, because the default settings of the most common editor produce it.
WarningPitfall
A restored workspace hides missing code. RStudio restores .RData into every new session by default, so an object you created by hand last month is still there, and a script that uses it runs without complaint. On anyone else’s machine, or in a fresh session, it fails, or finds a different object of the same name. Turn off workspace restoring in the global options, and run the analysis with Rscript before you believe it works.
2.4.1 Worked example: break it, then fix it
The first row of the table is the easiest to see. The function below computes a bootstrap 95 percent confidence interval for mean ejection fraction in the book’s running study, the HF-HOME trial, and runs it twice.
baseline <- read.csv(
  file.path('..', 'data', 'raw_data', 'hfhome', 'baseline.csv'),
  colClasses = c(patient_id = 'character')
)
ef <- baseline$ef_pct[!is.na(baseline$ef_pct)]

boot_ci <- function(x, reps = 2000) {
  means <- replicate(reps, mean(sample(x, replace = TRUE)))
  quantile(means, c(0.025, 0.975))
}

run_1 <- boot_ci(ef)
run_2 <- boot_ci(ef)
round(rbind(run_1, run_2), 2)
#>        2.5% 97.5%
#> run_1 40.95 42.19
#> run_2 40.98 42.20
identical(run_1, run_2)
#> [1] FALSE
Nothing failed. Both intervals are plausible, and they differ only in a late decimal place (the values change each time this page is built). That is why the omission survives. The analyst who reruns the script before a revision sees a slightly different number. He or she has no way to tell drift from a change in the data. The fix is one line, and the check that proves it is another.
TipVerification
Turn ‘the two runs agree’ into an assertion, so that a future edit that removes the seed stops the script instead of shifting a number.
In your own project, the stronger form of this check is to run the whole analysis twice in fresh sessions and compare the outputs file by file, for example with tools::md5sum().
The same approach scales from one function to a whole project: run it twice, in clean sessions, and compare. That is also the right way to use a model or a coding agent for an audit, because running the code shows failures that reading it cannot.
ImportantLLM prompt
A model reading a script can only guess what will fail; an agent that runs it in a clean session can show you.
Context.
analysis/run.Rin this R project readsdata/raw/and writesoutput/; the project has arenv.lock. You are a coding agent with a shell. Run only against the synthetic files indata/synthetic/.Constraints. Do not edit any file in the project and do not install packages outside the project library. Run the script twice with
Rscript --vanilla, in the project’s container if it has one.Criteria. Report every reproducibility failure you observe, classified as missing seed, unpinned version, manual step, hidden global state, or machine dependency, with the evidence for each (the error message, or the files whose checksums differ between the two runs) and the line responsible. If the script fails, stop and report; do not fix it.
Failure mode. A model that only reads the script flags the obvious gaps (no seed, a hard-coded path) and misses what shows only at run time: a file present only on your disk, an object supplied by .Rprofile, a nondeterministic parallel step. An agent told to ‘make it run’ may edit the script until it does, hiding the failure it found. Check. Confirm with git status that nothing changed, then rerun the script twice yourself and compare the outputs with tools::md5sum(). Record the model, the date, and the prompt in the project log (Habit 12); the agent sees synthetic data only (Section 12.3).
2.4.2 Exercises
- Audit the script below (display-only) against
- List each failure, the line that shows it, and the fix.
NoteSolution
| Line | Failure | Fix |
|---|---|---|
| 1 | Hidden global state: the script depends on a saved workspace | Delete the line; create every object in code |
| 2 | Unpinned version: nothing records which dplyr was used |
renv::snapshot() and commit renv.lock
|
| 3 | Machine dependency: an absolute path on one person’s computer | A path relative to the project, such as file.path('data', 'raw', ...)
|
| 3 | Manual step: hf_final_v3.csv is a derived file with no script that made it |
Read the raw export and derive the file in code |
| 4 | Manual step: the keep column was set by hand |
Replace it with a filter that states the exclusion rule |
| 5 | Missing seed |
set.seed() before the bootstrap |
The _v3 suffix is itself evidence: two earlier versions existed, and nothing says how they differ.
NoteCheck
Question. Of the six failures in 1, which ones produce an error, and which a different number?
Answer. Hidden global state and machine dependencies usually produce an error on another machine (an object or a file is not found), which is the cheap case. A missing seed, an upgraded package, and a stale intermediate produce a different number and no error, which is the expensive case (Habit 8). A manual step can produce either: an error if the derived file is absent, a wrong number if an old copy is present.
2.5 Why it is worth the cost
Most arguments for reproducibility are framed in terms of scientific virtue. They work for some audiences and not others. The self-interested argument is more durable. Reproducibility serves the analyst six months from now, and the PI who will need the analysis again. Table 2.5 sets out three events that happen on most projects.
| Event | Without a reproducible compendium | With one |
|---|---|---|
| Six months after submission, a reviewer asks for the primary analysis with a different exclusion criterion | A week reconstructing what was done, and doubt that it matches what was submitted | Half an hour: change one filter, rebuild, compare with the tagged submission |
| You discover that a unit conversion in step 7 was wrong | You cannot tell which other results, in this or other analyses, used the same step | Fix it, rebuild, and report exactly which numbers changed |
| A new postdoc takes over the project | A month learning what was done, much of it learned wrong | They rebuild the analysis on day one and start contributing |
The cost is highest at the start of a project, and the savings recur at every event.
The argument now has a second, external form. Since 2023 the National Institutes of Health (NIH) has made a Data Management and Sharing Plan a term of its awards for research that generates scientific data. Federal public-access policy also now reaches from publications to the data beneath them. As a result, the work of producing a reusable dataset, runnable code, and a declared environment falls to the analyst rather than to administrators. Chapter 34 takes up the specific policies and the practices that satisfy them.
2.5.1 Exercises
- Draft a short email to a skeptical PI explaining why reproducibility is in the group’s interest. Use two events from the group’s own recent history, in the form of Table 2.5.
NoteSolution
A model answer has four parts. It opens with the request (‘I would like to spend two days putting the readmissions analysis into a compendium’). It names two real events, with their cost in time (‘the revision in March took me eight days, most of them spent reconstructing the exclusions’). It states what the same event would cost afterward (‘a one-line change and a rebuild’). It ends with what the PI must do, which is usually nothing. An email that argues from scientific virtue, or that lists tools before naming an event the PI remembers, has missed the audience.
NoteCheck
Question. A PI says the project is small and will never be revisited. Which row of Table 2.5 is the strongest reply?
Answer. Usually the first. Almost every submitted paper is revisited at least once, by reviewers, and the reviewer’s request arrives after the analyst has moved on to other work. The cost of that one event, without a compendium, typically exceeds the cost of building the compendium in the first place.
2.6 Reproducibility is not correctness
A reproducible analysis can still be wrong. If your code implements the wrong test, you will reproducibly compute the wrong p-value. Reproducibility ensures only that running the code twice gives the same answer, not that the answer is right.
Conversely, a correct analysis can fail reproducibility. If the seed was not set, the bootstrap interval differs between runs, as the worked example showed. If package versions are unpinned, a function’s output may change. The analysis is correct in the methodological sense, but the published numbers are not exactly recoverable.
The two qualities are independent, and both are necessary. Tools address reproducibility; statistical training addresses correctness. The Reinhart and Rogoff case shows both at once. The spreadsheet error was a reproducibility failure. The weighting was a question of correctness, and it only became visible once the analysis could be rebuilt.
NoteCheck
Question. An analysis is fully reproducible: pinned environment, executable code, versioned data, one command to rebuild every number. It also dichotomizes a continuous outcome at the median, which costs power and makes the effect estimate depend on the sample. What has reproducibility bought, and what has it not?
Answer. It has bought the ability to find out. It has not made the analysis right, and nothing about the infrastructure will.
Reproducibility supplies legibility. The dichotomization is in the code, at a specific line, in a form a reviewer can point at. In an irreproducible analysis the same decision is invisible, described in the methods as ‘patients were classified as high or low’ with no way to see the cut point or how it was chosen. The error exists either way; only one version is auditable. It also makes the fix cheap: changing one line and rebuilding gives the corrected result in minutes.
A fully reproducible pipeline can produce a reliably wrong answer, and its polish can be mistaken for authority. A reviewer impressed by the Docker image and the lockfile may look less closely at the model. That is why the book puts Chapter 32 last rather than treating the infrastructure as the goal.
2.7 Rules of thumb
- Habit 1: the compendium is the unit. Code, data, and environment travel together; any two without the third cannot be rerun.
- Habit 2: raw data are evidence; derived data are a build product. Every manual step is either scripted or documented as raw input.
- Habit 8: a bug that produces a plausible number is the expensive kind. Both cases in this chapter ran without error; write the check that makes the quiet failure loud.
2.8 Cumulative practice
2.8.1 A replication exercise
The rest of this chapter has shown you two failures from the outside: what Baggerly and Coombes found in the Duke genomics case, and what Herndon found in Reinhart and Rogoff’s spreadsheet. Both took months, because neither original team had made its compendium available. The reconstruction itself was most of the cost. The exercise below puts you on the other side of that cost, against a paper that at least tried to avoid it. That is, the obstacles you log are those that remain even when code and data are public.
Choose a published paper in your own field that deposits both its code and its data openly, as a condition of publication rather than an informal courtesy. The surest way to find one is to pick a venue that states this as a policy you can check. Three kinds of venue qualify. The first is a Registered Report in a journal whose author guidelines require open data and code for that article type. The second is a journal that mandates data and code availability statements with working repository links (not merely ‘data available on request’). The third is a repository that itself requires deposited materials as a condition of indexing. Verify the policy on the journal’s or repository’s own page before you commit to a paper. A data availability statement that turns out to mean ‘contact the authors’ is common. It is worth ruling out early, before you have invested an afternoon.
With a paper in hand, reproduce one figure or one table, not the whole analysis. Pick one with enough numeric content that ‘matches’ and ‘does not match’ are not matters of eyeballing. Examples are a table of coefficients, a Kaplan-Meier curve with numbers you can read off, or a bar chart with labeled values. Work only from what the paper’s own compendium provides. That means its code, its deposited data (or the access procedure it documents), and its stated software versions, in that order. Do not consult the authors, and do not patch a failure with a guess about what they must have meant. Log a step you cannot complete from the deposited materials as an obstacle.
Keep a running log as you work, with one entry per obstacle. Tag each entry four ways. The first tag is the leg of Figure 2.2 it belongs to (code, data, or environment). The second is the specific failure from 1 it resembles, if any. The third is what you did to get past it (or that you could not). The fourth is whether the final number you obtained matches the paper’s reported figure or table, and if not, by how much and in which direction. An obstacle log that reads ‘the script needed dplyr, which was not pinned to a version; I installed the current one and it ran’ is far more useful later than one that reads only ‘had some package issues’. Finish by classifying what you tested against Table 2.1. An exact reproduction from the authors’ own data and code is a test of methods reproducibility. Nothing in this exercise tests whether the finding would replicate in a new sample.
There is no single correct result to check against, and the solution below describes a good log, not a target number. What counts as success varies by paper. Some published compendia let you rebuild a figure to the pixel. Some let you get within rounding error after fixing three unpinned versions. Some defeat you entirely despite a stated open-data policy, and that is itself a finding worth reporting. Log each outcome with the same care; the obstacle log is the deliverable.
- Cumulative (uses the whole chapter). Find a published paper in your field with public code and data, and try to reproduce one figure or table. Log every obstacle, classify each against 1 and Table 2.3, and state which kind of reproducibility (Table 2.1) your attempt tested. Use the fuller framing above if you have not already chosen a paper.
- On your own work (no key). Take the last analysis you wrote. List every piece of information that is not in the script but would be needed to reproduce its output, and for each say how you would capture it in code, the README, or the lockfile.
NoteSolution
A good log names each obstacle concretely (‘ggplot2 3.5 changed the default legend position, so the figure differs’; ‘the cleaned file is supplied, the raw file is not’). Most attempts meet at least one unpinned version and one missing manual step. An attempt that reproduces the figure exactly from the supplied code and data tested methods reproducibility; it says nothing about whether the finding replicates.
2.9 Cheat sheet
| Ask of any analysis | Leg | Where the answer lives |
|---|---|---|
| Does one command rebuild every number from raw data? | Code | A script or pipeline (Chapter 24) |
| Is every exclusion a filter with a stated rule? | Code | The cleaning script |
| Are the raw data present, or is the access procedure documented? | Data |
data/raw/ or the README |
| Is the raw file unchanged since receipt? | Data | A recorded checksum |
| Are R and every package version recorded? | Environment |
renv.lock (Chapter 9) |
| Is everything beneath R pinned? | Environment | A Dockerfile (Chapter 10) |
| Is every random step seeded? | Code |
set.seed() in the script |
| Does it run in a fresh session on another machine? | All three |
Rscript, a container, or a colleague |
2.10 Further reading
- (Goodman et al., 2016), the taxonomy of reproducibility used in this chapter.
- (Marwick et al., 2018), the research-compendium framing this book uses.
- (National Academies of Sciences, Engineering, and Medicine, 2019), the consensus report on definitions, causes, and remedies.
2.11 Prerequisites answers
- A reproducible analysis is one where a collaborator given the same data and code can obtain identical output on their own machine. Replicable is stronger: it means the conclusions hold when the study is repeated with new data. Reproducibility is about the computational chain; replicability is about the scientific claim. Methods reproducibility is the floor the rest of this book is about.
- Code, data, and the computational environment (R version, package versions, operating system, and any system dependencies). Without all three, results may differ silently on another machine.
renv.lockand a Dockerfile (or Apptainer image) are the standard tools for capturing the environment. - Reproducible means the analysis can be run again and produce the same answer. A correct analysis uses a valid statistical method on appropriate data. A reproducible analysis can still be wrong (for example, it consistently applies the wrong test); a correct analysis can fail reproducibility if random seeds are not set or package versions are not pinned. Both qualities are necessary; neither implies the other.